
Introduction
In the previous article, we studied Deep Learning. One thing that I believe is that if we can correlate anything with us or our life, there are greater chances of understanding the concept. So I will try to explain everything by relating it to humans.
What is Data?
Data are individual units of information. A datum describes a single quality or quantity of some object or phenomenon. In analytical processes, data are represented by variables. Although the terms "data", "information" and "knowledge" are often used interchangeably, each of these terms has a distinct meaning.
Data is measured, collected and reported, and analyzed, whereupon it can be visualized using graphs, images or other analysis tools. Data as a general concept refers to the fact that some existing information or knowledge is represented or coded in some form suitable for better usage or processing.
Everything and anything can be called data. Data is an abstract term, which can be used for each and every type of data. The amount of data that is generated on a daily basis can be estimated by seeing the following figures:
- Google: processed 24 Peta Bytes of data every data per day
- Facebook: 10 million photos uploaded every hour
- Youtube: 1 hour of video uploaded every second
- Twitter: 400 million tweets per day
- Astronomy: Satellite Data is in hundreds of petabytes
Note: 1 petabyte is 1 million megabytes or 1 quadrillion bytes or 1000 trillion bytes or 1e-15 bytes
So from the above values, you can very easily understand that on a daily basis we produce around 1 GB or GigaByte of Data. Even the above-written figures are also a type of data.
What is Data Science?
Data Science is a detailed study of the flow of information from the colossal amounts of data present in an organization’s repository. It involves obtaining meaningful insights from raw and unstructured data which is processed through analytical, programming, and business skills.
Data science is a "concept to unify statistics, data analysis, machine learning, and their related methods" in order to "understand and analyze actual phenomena" with data. It employs techniques and theories drawn from many fields within the context of mathematics, statistics, computer science, and information science.
Turing award winner Jim Gray imagined data science as a "fourth paradigm" of science (empirical, theoretical, computational and now data-driven) and asserted that "everything about science is changing because of the impact of information technology" and the data deluge. In 2015, the American Statistical Association identified database management, statistics, and machine learning, and distributed and parallel systems as the three emerging foundational professional communities.
What is Data Munging?
Data wrangling sometimes referred to as data munging, is the process of transforming and mapping data from one "raw" data form into another format with the intent of making it more appropriate and valuable for a variety of downstream purposes such as analytics. A data wrangler is a person who performs these transformation operations.
Raw data can be unstructured and messy, with information coming from disparate data sources, mismatched or missing records, and a slew of other tricky issues. Data munging is a term to describe the data wrangling to bring together data into cohesive views, as well as the janitorial work of cleaning up data so that it is polished and ready for downstream usage. This requires good pattern-recognition sense and clever hacking skills to merge and transform masses of database-level information. If not properly done, dirty data can obfuscate the 'truth' hidden in the data set and completely mislead results. Thus, any data scientist must be skillful and nimble at data munging in order to have accurate, usable data before applying more sophisticated analytical tactics.
Difference between Business Intelligence and Data Science
| Features | Business Intelligence (BI) | Data Science |
| Data Sources | Structured (Usually SQL, often Data Warehouse) | Both Structured and Unstructured (logs, cloud data, SQL, NoSQL, text) |
| Approach | Statistics and Visualization | Statistics, Machine Learning, Graph Analysis, Neuro-linguistic Programming (NLP) |
| Focus | Past and Present | Present and Future |
| Tools | Pentaho, Microsoft BI, QlikView, R | RapidMiner, BigML, Weka, R |
| Coining of Term | Business Analytics has been used since the late 19th Century when it was put in place by Frederick Winslow Taylor | DJ Patil and Jeff Hammerbacher who were working in LinkedIn and Facebook respectively, first coined the term in 2008 |
| Concept | Use of statistical concepts to extract insights from business data | The interdisciplinary field of data inference, algorithm building, and systems to gain insights from data |
| Top 5 Industries |
1. Financial
2. Technology
3. Mix of fields
4. CRM/Marketing
5. Retail
|
1. Technology
2. Financial
3. Mix of fields
4. Internet-based
5. Academic
|
| Coding | It does not involve much coding. More statistics oriented | Coding is used widely. The field is a combination of traditional analytics practices with sound knowledge of computer science |
| Language Recommendations | C/C++/C#, JAVA, MATLAB, PYTHON, R, SAS, SCALA, SQL | C/C++/C#, HASKELL, JAVA, MATLAB, PYTHON, R, SAS, SCALA, SQL, JULIA, STATA |
| Statistics | The whole analysis is based on statistical concepts | Statistics is used at the end of analysis following algorithm building and coding |
| Data Needed | Predominantly structured data | Both structured and unstructured data |
The following image shows a comparison between the popularity of Business Intelligence and Data Science.
Legend:
Blue: Business Intelligence
Red: Data Science
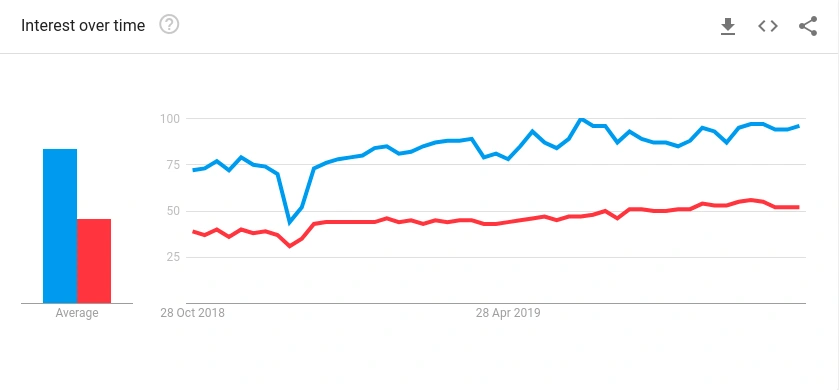
Source: Google Trends
Difference between Machine Learning and Data Science
| Features | Machine Learning | Data Science |
| Scope | Accurately classify or predict the outcome for new data point by learning patterns from historical data using mathematical models | Create insights from data dealing with all real-world complexities. This includes tasks like understand requirements extracting data, etc. |
| Input Data | Input data for ML will be transformed specifically for algorithms used. Feature scaling, word embedding or adding polynomial features are some examples | Most of the input data is generated as human consumable data which is to be read or analyzed by humans like tabular data or images |
| System Complexity |
1. Major complexity is with algorithms and mathematical concepts behind that
2. Ensemble models will have more than one ML model and each will have a weighted contribution on the final output
|
1. Components for handling unstructured raw data coming
2. A lot of moving components typically scheduled by an orchestration layer to synchronize independent jobs
|
| Preferred Skill Set |
1. Strong Maths understanding
2. Python/R programming
3. Data wrangling with SQL Model specific visualization
|
1. Domain expertise
2. ETL and data profiling
3. String SQL
4. NoSQL system standard reporting/visualization
|
| Hardware Specification |
1. GPUs are preferred for intensive vector operations
2. More powerful versions like TPUs are on the way
|
1. Horizontally scalable systems preferred to handle massive data
2. High RAM and SSDs used to overcome I/O bottleneck
|
The following image shows a comparison between the popularity of Machine Learning and Data Science.
Legend:
Blue: Machine Learning
Red: Data Science
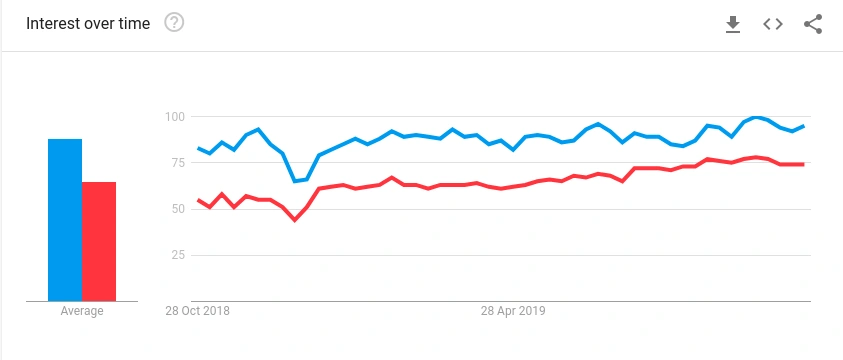
Source: Google Trends
Difference between Data Science and Artificial Intelligence
| Factors | Data Science | Artificial Intelligence |
| Scope | Involves various underlying data operations | Limited to the implementation of ML algorithms |
| Type of Data | Structured and Unstructured | Standardized in the form of embeddings and vectors |
| Tools | R, Python, SAS, SPSS, TensorFlow, Keras, Scikit- Learn | Scikit-Learn, Kaffe, PyTorch, TensorFlow, Shogun, Mahout |
| Applications | Advertising, Marketing, Internet Search Engines | Manufacturing, Automation, Robotics, Transport, Healthcare |
The following image shows a comparison between the popularity of Artificial Intelligence and Data Science.
Legend:
Blue: Data Science
Red: Artificial Intelligence
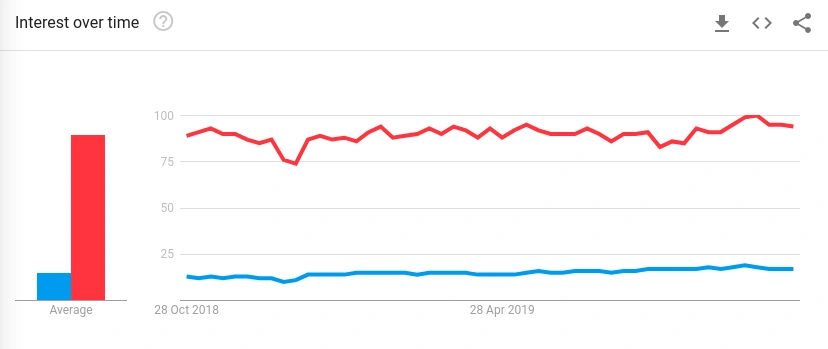
Source: Google Trends
Advantages/Features of Data Science
1. It detects and corrects the errors from data sets with the help of data cleansing. This helps in improving the quality of data and consecutively benefits both customers and institutions such as banks, insurance, and finance companies.
2. It removes duplicate information from data sets and hence saves large amount of memory space. This decreases the cost to the company.
3. It helps in displaying relevant advertisements on the online shopping websites based on historic data and purchase behavior of the users. Machine learning algorithms are applied to the same. This helps in increasing the revenue and productivity of the companies.
4. It reduces banking risks by identifying probable fraudulent customers based on historic data analysis. This helps institutes in deciding whether to issue loans or credit cards to the applicants or not.
5. It is used by security agencies for surveillance and monitoring purposes based on information collected by huge number of sensors. This helps in preventing any wrongdoings and/or calamities.
Disadvantages/Shortcomings of Data Science
1. This may breach the privacy of the customers as their information such as purchases, online transactions, subscriptions are visible to their parent companies. The companies may exchange these useful customer databases for their mutual benefits.
2. The cost of data analytics tools varies based on applications and features supported. Moreover, some of the data analytics tools are complex to use and require training. These increases cost to the company willing to adopt data analytics tools or software.
3. The information obtained using data analytics can also be misused against a group of people in certain countries or community or caste.
4. It is very difficult to select the right data analytics tools. This is due to the fact that it requires knowledge of the tools and their accuracy in analyzing the relevant data as per applications. This increases the time and cost to the company.
What are the skills required to be a Data Scientist?
A Data Scientist is a professional with the capabilities to gather large amounts of data to analyze and synthesize the information into actionable plans for companies and other organizations. Following are some requirements that need to be met so as to become a good Data Scientist:
1. Mathematics Expertise
At the heart of mining data insight and building data product are the ability to view the data through a quantitative lens. There are textures, dimensions, and correlations in data that can be expressed mathematically. Finding solutions utilizing data becomes a brain teaser of heuristics and quantitative technique. Solutions to many business problems involve building analytic models grounded in hard math, where being able to understand the underlying mechanics of those models is key to success in building them. Also, a misconception is that data science is all about statistics. While statistics are important, it is not the only type of math utilized.
First, there are two branches of statistics – classical statistics and Bayesian statistics. When most people refer to stats they are generally referring to classical stats, but knowledge of both types is helpful. Furthermore, many inferential techniques and machine learning algorithms lean on the knowledge of linear algebra.
For example, a popular method to discover hidden characteristics in a data set is SVD, which is grounded in matrix math and has much less to do with classical stats. Overall, it is helpful for data scientists to have breadth and depth in their knowledge of mathematics.
2. Technology and Hacking
First, let's clarify that we are not talking about hacking as in breaking into computers. We're referring to the tech programmer subculture meaning of hacking – i.e., creativity and ingenuity in using technical skills to build things and find clever solutions to problems.
Why is hacking ability important? Because data scientists utilize technology in order to wrangle enormous data sets and work with complex algorithms, and it requires tools far more sophisticated than Excel. Data scientists need to be able to code — prototype quick solutions, as well as integrate with complex data systems. Core languages associated with data science include SQL, Python, R, and SAS. On the periphery are Java, Scala, Julia, and others. But it is not just knowing language fundamentals. A hacker is a technical ninja, able to creatively navigate their way through technical challenges in order to make their code work.
Along these lines, a data science hacker is a solid algorithmic thinker, having the ability to break down messy problems and recompose them in ways that are solvable. This is critical because data scientists operate within a lot of algorithmic complexity. They need to have a strong mental comprehension of high-dimensional data and tricky data control flows. Full clarity on how all the pieces come together to form a cohesive solution.
3. Strong Business Acumen
It is important for a data scientist to be a tactical business consultant. Working so closely with data, data scientists are positioned to learn from data in ways no one else can. That creates the responsibility to translate observations to shared knowledge and contribute to strategy on how to solve core business problems. This means a core competency of data science is using data to cogently tell a story. No data-puking – rather, present a cohesive narrative of problem and solution, using data insights as supporting pillars, that lead to guidance.
Having this business acumen is just as important as having acumen for tech and algorithms. There needs to be clear alignment between data science projects and business goals. Ultimately, the value doesn't come from data, math, and tech itself. It comes from leveraging all of the above to build valuable capabilities and has strong business influence.
In short, the skills required to be a data scientist are:
- Statistics
- Programming skills
- Critical thinking
- Knowledge of AI, ML, and Deep Learning
- Comfort with math
- Good Knowledge of Python, R, SAS, and Scala
- Communication
- Data Wrangling
- Data Visualization
- Ability to understand analytical functions
- Experience with SQL
- Ability to work with unstructured data
Ankur MistryPosted Dec 24, 2019, 9:45 PM
Good stuff to read, thank you Rohit Gupta for sharing
Rushi MehtaPosted Dec 24, 2019, 6:25 AM
Nice Article and also its clear the concept of Data Science
Sourav Kumar DasPosted Oct 28, 2019, 11:43 PM
Nice informative Article Sir.
Onkar SharmaPosted Oct 24, 2019, 12:51 PM
Nice Article sir, Thanks for sharing this valuable information with us...
Pankajkumar PatelPosted Oct 23, 2019, 11:18 PM
Nice article
Elavarasan RPosted Oct 23, 2019, 7:08 PM
Great. Nice article really helpful.
Sundaram SubramanianPosted Oct 23, 2019, 4:43 AM
Fabulous. Well written. You are a tech Enthusiast. I am learning many things from your articles.