In enterprise AI deployments, agents do not operate in a vacuum. They interact with legacy internal systems, third-party SaaS platforms, and external databases. These external dependencies are inherently unreliable. When a multi-agent system scales to thousands of concurrent users, a simple API timeout can cascade into a thundering herd problem, bringing down both your AI infrastructure and the target API. This article provides an end-to-end guide to implementing robust retry logic with exponential backoff and jitter in Python. We will apply this to a real-world enterprise use case: building a Multi-Agent LangGraph RAG system with persistent memory and state for an e-commerce customer support platform.
Part 1: The Theory of Resilient API Calls
Before writing code, we must understand the mechanics of resilient network calls.
1. Exponential Backoff
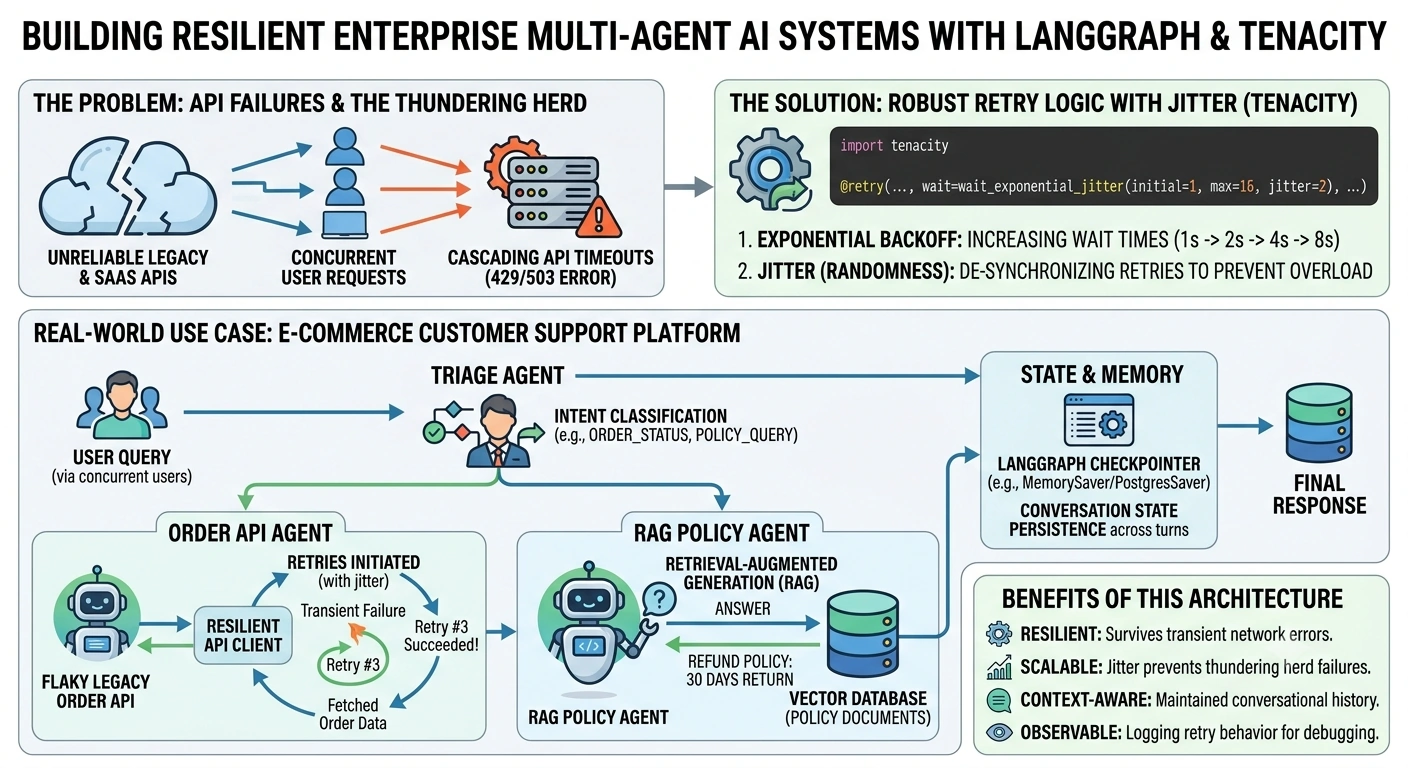
When an API returns a 429 Too Many Requests or 503 Service Unavailable, immediately retrying is counterproductive. Exponential backoff increases the wait time between retries exponentially.
2. Jitter (The Thundering Herd Antidote)
If 1,000 LangGraph agents experience an API failure at the exact same millisecond, exponential backoff alone means all 1,000 agents will retry at the exact same millisecond 1 second later, crashing the API again.
Jitter adds randomness to the delay, desynchronizing the retries.
In Python, the enterprise standard for implementing this is the tenacity library, which handles the complex math and edge cases (like overflow and maximum caps) elegantly.
Part 2: The Real-World Use Case
Scenario: An enterprise e-commerce company uses an AI support system to handle customer queries.
The Problem: The AI needs to fetch real-time order data from a legacy, highly flaky internal Order API. It also needs to answer policy questions using a RAG (Retrieval-Augmented Generation) pipeline over a vector database.
The Architecture:
Triage Agent: Analyzes the user's intent and routes the workflow.
Order API Agent: Uses our resilient retry client to fetch order data.
RAG Policy Agent: Retrieves refund/shipping policies from a vector store.
State & Memory: LangGraph Checkpointer ensures the conversation state and memory persist across multiple turns.
Part 3: Implementing the Resilient API Client
First, let's build the resilient API wrapper. We will use tenacity to implement exponential backoff with full jitter.
import time
import random
import logging
import httpx
from tenacity import (
    retry,
    stop_after_attempt,
    wait_exponential_jitter,
    retry_if_exception_type,
    before_sleep_log,
)

# Configure logging to observe the retry behavior
logging.basicConfig(level=logging.INFO, format='%(asctime)s - %(levelname)s - %(message)s')
logger = logging.getLogger(__name__)

class TransientAPIError(Exception):
    """Custom exception for transient network/API errors."""
    pass

# Mocking a flaky legacy API for demonstration purposes
_api_call_count = 0

def _mock_flaky_legacy_api(order_id: str) -> dict:
    global _api_call_count
    _api_call_count += 1

    # Simulate transient failures (fails first 2 times, succeeds on 3rd)
    if _api_call_count < 3:
        logger.warning(f"API Call #{_api_call_count} for Order {order_id} failed with 503 Service Unavailable")
        raise TransientAPIError("503 Service Unavailable")

    logger.info(f"API Call #{_api_call_count} for Order {order_id} succeeded.")
    return {
        "order_id": order_id,
        "status": "Shipped",
        "carrier": "FedEx",
        "tracking_number": "1Z999AA10123456784",
        "estimated_delivery": "2026-07-26"
    }

# THE MAGIC: Exponential Backoff + Jitter
@retry(
    stop=stop_after_attempt(5),
    # wait = (2^attempt * 1) + random(0 to 2)
    wait=wait_exponential_jitter(initial=1, max=16, jitter=2),
    retry=retry_if_exception_type(TransientAPIError),
    before_sleep=before_sleep_log(logger, logging.WARNING),
    reraise=True
)
def get_order_details_resilient(order_id: str) -> dict:
    """
    Fetches order details with automatic exponential backoff and jitter.
    In production, replace _mock_flaky_legacy_api with an actual httpx/requests call.
    """
    # Example production code:
    # response = httpx.get(f"https://internal-legacy-api.corp/orders/{order_id}", timeout=5.0)
    # if response.status_code in [429, 500, 502, 503, 504]:
    #     raise TransientAPIError(f"Transient error: {response.status_code}")
    # return response.json()

    return _mock_flaky_legacy_api(order_id)
Why this implementation is enterprise-grade
wait_exponential_jitter: Prevents the thundering herd.
max=16: Caps the maximum wait time so the user isn't left waiting for 5 minutes on the 10th retry.
retry_if_exception_type: We only retry on transient errors (503, 429). We do not retry on 400 Bad Request or 401 Unauthorized.
before_sleep_log: Provides crucial observability into the agent's retry behavior.
Part 4: Building the LangGraph Multi-Agent RAG System
Now, we integrate this resilient tool into a LangGraph multi-agent architecture with persistent memory.
1. Define the State and Memory
LangGraph uses a State object to pass data between nodes. We will use a Checkpointer to save this state to a database (we'll use MemorySaver for the example, but in production, you would use PostgresSaver).
from typing import TypedDict, Annotated, Sequence
from langchain_core.messages import BaseMessage, HumanMessage, AIMessage
from langgraph.graph import StateGraph, END
from langgraph.checkpoint.memory import MemorySaver
from langchain_openai import ChatOpenAI

# Define the Graph State
class AgentState(TypedDict):
    messages: Annotated[Sequence[BaseMessage], "The conversation history"]
    current_intent: str  # Tracks the routed intent
    order_data: dict     # Stores fetched order data
    user_id: str         # Used for memory partitioning
2. Define the Tools (The Multi-Agent Capabilities)
from langchain_core.tools import tool
from langchain_core.prompts import ChatPromptTemplate, MessagesPlaceholder

# Tool 1: The Resilient Order API
@tool
def fetch_order_status(order_id: str) -> str:
    """Fetches real-time order status from the legacy internal API."""
    try:
        data = get_order_details_resilient(order_id)
        return f"Order {data['order_id']} is currently {data['status']} via {data['carrier']}. Tracking: {data['tracking_number']}"
    except Exception as e:
        return f"Failed to fetch order after multiple retries: {str(e)}"

# Tool 2: The RAG Policy Retriever
@tool
def search_refund_policy(query: str) -> str:
    """Searches the vector database for company refund and shipping policies."""
    # In production, this queries a FAISS/Pinecone/Milvus vector store
    policies = {
        "refund": "Customers have 30 days to return items for a full refund. Shipping costs are non-refundable.",
        "shipping": "Standard shipping takes 5-7 business days. Expedited takes 2-3 business days."
    }
    # Simple mock retrieval
    if "refund" in query.lower():
        return policies["refund"]
    return policies["shipping"]
3. Define the Agent Nodes
# Initialize LLMs
router_llm = ChatOpenAI(model="gpt-4o", temperature=0)
worker_llm = ChatOpenAI(model="gpt-4o", temperature=0)

# Node 1: Triage / Router Agent
def triage_node(state: AgentState):
    """Routes the user query to the correct specialized agent."""
    messages = state["messages"]
    prompt = ChatPromptTemplate.from_messages([
        ("system", "You are a triage agent. Classify the user intent as either 'ORDER_STATUS' or 'POLICY_QUERY'."),
        MessagesPlaceholder(variable_name="messages"),
        ("human", "Intent:")
    ])

    chain = prompt | router_llm
    response = chain.invoke({"messages": messages})

    intent = "ORDER_STATUS" if "ORDER" in response.content.upper() else "POLICY_QUERY"
    return {"current_intent": intent}

# Node 2: Order API Agent
def order_agent_node(state: AgentState):
    """Handles order-specific queries using the resilient API tool."""
    messages = state["messages"]
    prompt = ChatPromptTemplate.from_messages([
        ("system", "You are an order support agent. Use the fetch_order_status tool to get real-time data. Be concise."),
        MessagesPlaceholder(variable_name="messages")
    ])

    agent = worker_llm.bind_tools([fetch_order_status])
    chain = prompt | agent

    # Invoke LLM to decide if it needs to call the tool
    response = chain.invoke({"messages": messages})

    # If the LLM decides to call the tool, execute it
    if response.tool_calls:
        tool_call = response.tool_calls[0]
        tool_result = fetch_order_status.invoke(tool_call["args"])

        # Feed the tool result back to the LLM for a final user-facing response
        final_prompt = prompt + [("human", f"Tool result: {tool_result}\n\nGenerate the final response to the user.")]
        final_response = worker_llm.invoke(final_prompt.invoke({"messages": messages}).to_messages())
        return {"messages": [final_response], "order_data": {"fetched": True}}

    return {"messages": [response]}

# Node 3: RAG Policy Agent
def rag_agent_node(state: AgentState):
    """Handles policy queries using RAG."""
    messages = state["messages"]
    prompt = ChatPromptTemplate.from_messages([
        ("system", "You are a policy support agent. Use the search_refund_policy tool to answer questions accurately based on company policy."),
        MessagesPlaceholder(variable_name="messages")
    ])

    agent = worker_llm.bind_tools([search_refund_policy])
    chain = prompt | agent

    response = chain.invoke({"messages": messages})

    if response.tool_calls:
        tool_call = response.tool_calls[0]
        tool_result = search_refund_policy.invoke(tool_call["args"])

        final_prompt = prompt + [("human", f"Context from policy DB: {tool_result}\n\nGenerate the final response.")]
        final_response = worker_llm.invoke(final_prompt.invoke({"messages": messages}).to_messages())
        return {"messages": [final_response]}

    return {"messages": [response]}
4. Assemble the LangGraph Workflow
# Routing logic
def route_intent(state: AgentState) -> str:
    if state["current_intent"] == "ORDER_STATUS":
        return "order_agent"
    return "rag_agent"

# Build the Graph
workflow = StateGraph(AgentState)

# Add Nodes
workflow.add_node("triage", triage_node)
workflow.add_node("order_agent", order_agent_node)
workflow.add_node("rag_agent", rag_agent_node)

# Define Edges
workflow.set_entry_point("triage")
workflow.add_conditional_edges(
    "triage",
    route_intent,
    {
        "order_agent": "order_agent",
        "rag_agent": "rag_agent",
    }
)

# All worker nodes end the graph turn
workflow.add_edge("order_agent", END)
workflow.add_edge("rag_agent", END)

# Compile with Memory (Checkpointer)
# In production: from langgraph.checkpoint.postgres import PostgresSaver
# checkpointer = PostgresSaver.from_conn_string("postgresql://...")
memory = MemorySaver()
app = workflow.compile(checkpointer=memory)
Part 5: Execution and Observability
Let's run the system. We will use a thread_id to simulate a persistent conversation, demonstrating both the Memory and the Retry Logic.
def run_conversation():
    # Reset mock API counter for clean test
    global _api_call_count
    _api_call_count = 0

    config = {"configurable": {"thread_id": "user_12345_session_1"}}

    print("--- Turn 1: User asks about an order (Triggers Retries) ---")
    inputs = {"messages": [HumanMessage(content="Where is my order #994422?")], "user_id": "user_12345"}

    # Stream the execution to see the graph in action
    for event in app.stream(inputs, config, stream_mode="updates"):
        for node, output in event.items():
            if "messages" in output:
                for msg in output["messages"]:
                    if hasattr(msg, 'content') and msg.content:
                        print(f"[{node.upper()}]: {msg.content}")

    print("\n--- Turn 2: User asks a follow-up about refunds (Tests Memory & RAG) ---")
    # Because of the checkpointer, we don't need to pass the history!
    inputs_turn2 = {"messages": [HumanMessage(content="Can I get a refund if it's damaged?")]}

    for event in app.stream(inputs_turn2, config, stream_mode="updates"):
        for node, output in event.items():
            if "messages" in output:
                for msg in output["messages"]:
                    if hasattr(msg, 'content') and msg.content:
                        print(f"[{node.upper()}]: {msg.content}")

if __name__ == "__main__":
    run_conversation()
Expected Output & Observability
When you run this, the logs will beautifully illustrate the concepts we discussed:
--- Turn 1: User asks about an order (Triggers Retries) ---
2026-07-24 10:00:01 - WARNING - API Call #1 for Order 994422 failed with 503 Service Unavailable
2026-07-24 10:00:01 - WARNING - Retrying get_order_details_resilient in 1.45 seconds as it raised TransientAPIError: 503 Service Unavailable.
2026-07-24 10:00:02 - WARNING - API Call #2 for Order 994422 failed with 503 Service Unavailable
2026-07-24 10:00:02 - WARNING - Retrying get_order_details_resilient in 2.81 seconds as it raised TransientAPIError: 503 Service Unavailable.
2026-07-24 10:00:05 - INFO - API Call #3 for Order 994422 succeeded.
[ORDER_AGENT]: Your order #994422 is currently Shipped via FedEx. Your tracking number is 1Z999AA10123456784, and the estimated delivery is July 26, 2026.

--- Turn 2: User asks a follow-up about refunds (Tests Memory & RAG) ---
[RAG_AGENT]: Yes, you can get a refund if the item is damaged. According to our policy, customers have 30 days to return items for a full refund. Please note that original shipping costs are non-refundable.
Analyzing the Execution:
Jitter in Action: Notice the retry delays (1.45s, 2.81s). They are not exactly 1s and 2s. The jitter has successfully randomized the backoff, ensuring that if 1,000 users asked for order #994422 at the same time, their retries would be spread out over time, saving the legacy API from a DDoS-like crash.
State & Memory: In Turn 2, we didn't pass the previous messages. The LangGraph MemorySaver retrieved the context using the thread_id, allowing the RAG agent to understand the conversational flow seamlessly.
Multi-Agent Routing: The Triage node correctly identified Turn 1 as an ORDER_STATUS intent and Turn 2 as a POLICY_QUERY, routing them to the correct specialized tools without cross-contamination.
Conclusion: Enterprise Best Practices
When deploying LLM agents in enterprise environments, treating external API calls as "fire and forget" is a critical architectural flaw. By combining Tenacity's exponential backoff with jitter and LangGraph's stateful multi-agent routing, you achieve a system that is:
Resilient: Survives transient network blips and legacy system hiccups.
Scalable: Jitter prevents cascading failures during high-concurrency spikes.
Context-Aware: LangGraph memory ensures agents maintain conversational continuity across complex, multi-turn workflows.
Observable: Proper logging at the retry layer gives DevOps teams the visibility needed to debug production issues.

Join the conversation! Your thoughts help the community grow.