

🧠 Let's think about Performance
When you think about software performance, its more than just one part of the code. If its a Web application, the performance starts with the lowest layer of your infrastructure that is hardware, its resources (memory, space, network), the Web server, database, and then the code. Here is an article I wrote on this topic: Top 10 Tips For Building High Performance Websites .
This article focuses on API performance and how to architect an API project.
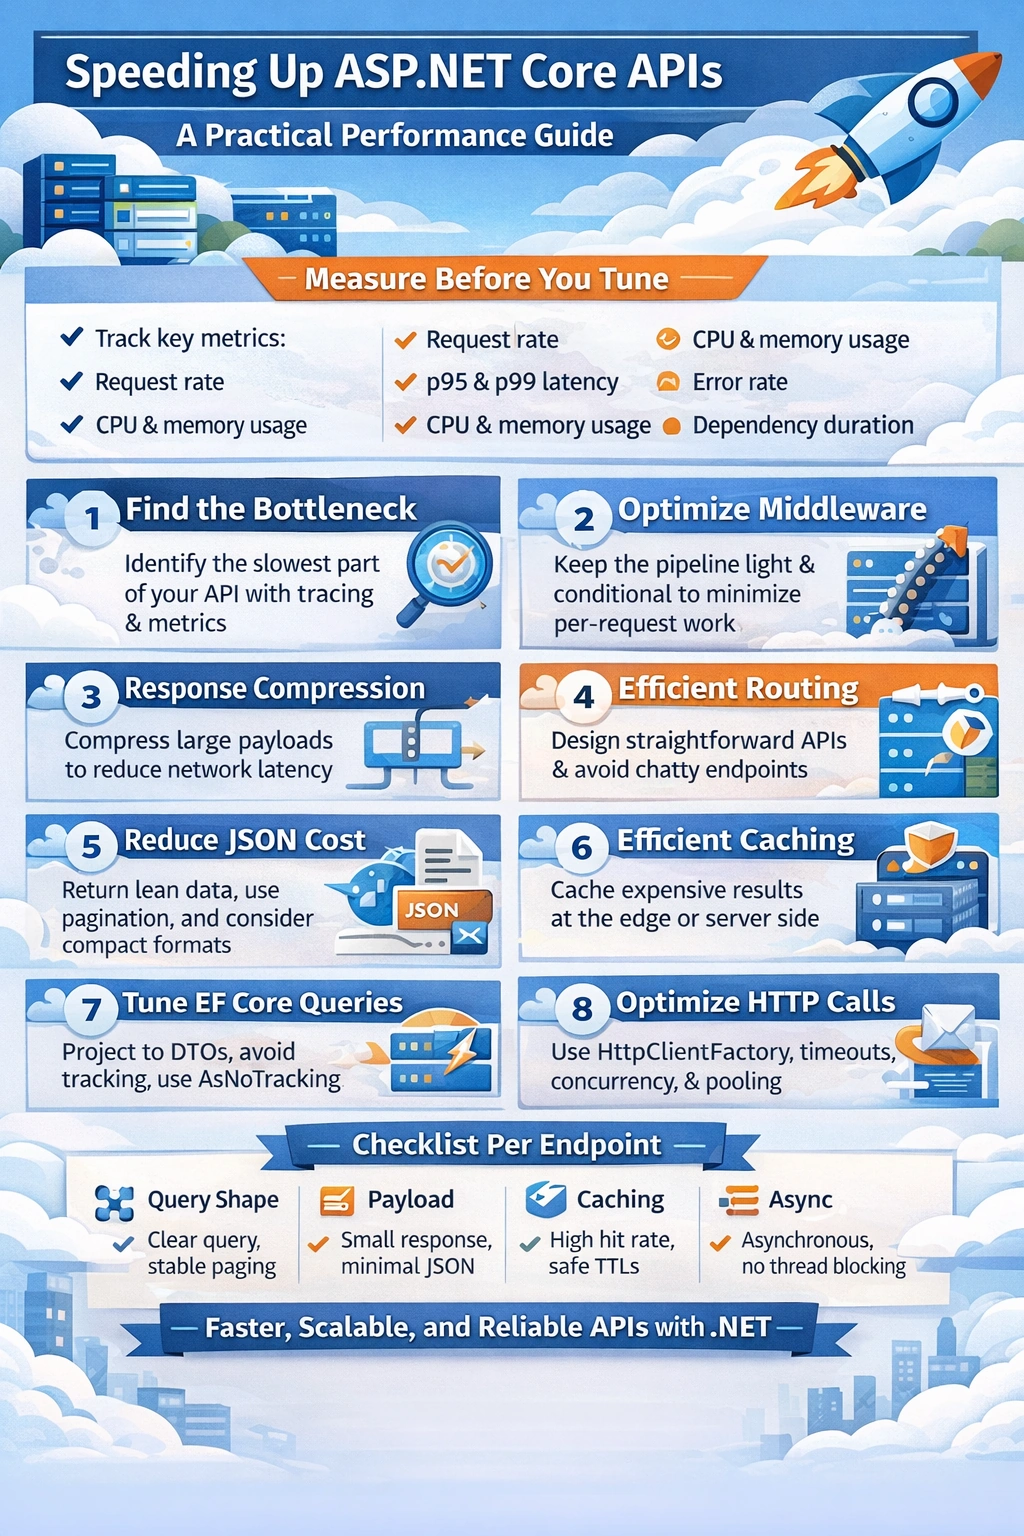
🎯 Step 1: Measure the right numbers before you tune
Before you start typing code, you must find the reason. You can start with running some analysis on your code. There are many tools available today including the Copilot you have in your IDE. If you do not use Copilot, I highly recommend spend few bucks and get a Copilot license. And the first thing you do is, ask Copilot to analyze your code.
Performance work fails when teams only look at average latency, because averages hide user pain and hide tail spikes.
Track these per endpoint and per dependency - Request rate, p50, p95, p99 latency, Error rate, CPU percent, Memory and GC time, Allocation rate, Thread pool starvation signals, Database duration and row counts, Outbound HTTP duration and error rate.
If you do not have distributed tracing, start there, because you will otherwise spend time optimizing the wrong layer. Logging alone is not observability, because it rarely shows timing structure across services.
🧱 Step 2: Fix the biggest problem first with a bottleneck map
In most real APIs, the time goes into one of these buckets:
Database queries and ORM overhead
Outbound HTTP calls
Serialization and payload size
Excessive allocations and GC pressure
Thread pool blocking caused by sync over async
Too much work in middleware or filters
Chatty endpoints that call many dependencies
A practical way to find the bottleneck is to pick a slow endpoint, capture a trace, and write down the percentage of time spent in each dependency. If 70 percent is the database, spending weeks micro optimizing JSON formatting is wasted effort.
⚙️ Step 3: Make the request pipeline smaller and cheaper
Prefer minimal middleware and avoid work for every request
Each middleware is a function call, and some middlewares do expensive work even when an endpoint does not need it. Make sure the expensive parts of your pipeline are conditional, and keep the common path thin.
Enable response compression when it helps
Compression reduces payload size and can reduce latency over slow networks, but it uses CPU, so it must be evaluated with real traffic. It tends to help more for large JSON responses and less for small payloads.
Avoid per request allocations in middleware
If your middleware creates strings, dictionaries, regex objects, or large objects per request, you are paying a GC tax at scale. Cache static data, use pooled structures when appropriate, and prefer pre compiled patterns for hot paths.
🧭 Step 4: Be intentional about routing and endpoint design
Avoid chatty endpoints
If the client needs five calls to render one view, your API is slow even if each call is “fast.” Consolidate into fewer endpoints that return exactly what the UI needs, but do not overfetch massive objects either, because big responses increase serialization time and memory.
Avoid overly generic endpoints on hot paths
Endpoints that take complex filter objects, dynamic sorts, and huge includes often generate complex queries and unpredictable plans. For hot paths, design explicit endpoints and explicit query shapes.
📦 Step 5: Reduce JSON cost and payload size
Serialization is not usually the top cost, but it becomes meaningful at high RPS or when payloads are large.
Practical tactics:
Return only the fields needed, avoid returning giant domain objects
Avoid cycles, avoid deep graphs, avoid unnecessary nested collections
Use pagination by default for collections
Avoid writing custom converters unless you have measured a real gain
If you control the client, consider whether you need JSON for everything. For internal service to service calls, gRPC can reduce payload size and CPU cost, but it introduces a different operational model, so treat it as an engineering decision, not a trend.
🗄️ Step 6: Caching, the only honest shortcut
Caching is the most effective performance tool when used correctly, because it eliminates work entirely.
Cache on the client and at the edge
If responses are cacheable, use proper cache headers and allow CDNs or gateways to serve responses without touching your API.
Use server side caching for expensive results
In memory caching is fast but limited to one instance, which is fine for single instance or when the data is truly per instance. Distributed caching is more suitable when you have multiple replicas and want consistent hit rates.
The key is invalidation and freshness. Cache what is either immutable, slowly changing, or acceptable to be slightly stale. Do not cache data where correctness depends on millisecond freshness unless you have a strong strategy.
🧠 Step 7: EF Core and database performance
Most API latency comes from the database layer, so improving query shape and reducing round trips usually beats any framework tweak.
Use AsNoTracking for read heavy queries
Tracking adds overhead and memory pressure. For read only queries, disable tracking.
var products = await db.Products
    .AsNoTracking()
    .Where(p => p.IsActive)
    .Select(p => new ProductDto(p.Id, p.Name, p.Price))
    .ToListAsync(ct);
Project to DTOs instead of loading full entities
Projection reduces materialization work and avoids bringing columns you do not need.
Avoid N plus 1 problems
If you see many similar queries per request, you are doing repeated lazy loading patterns. Prefer explicit includes when needed, but do not blindly include everything, because huge joins and cartesian explosions can be worse.
Use compiled queries for very hot paths
For endpoints hit extremely often, compiled queries can reduce overhead, but only use them after measurement, because maintainability matters.
Make sure the database has the right indexes
App code cannot out run missing indexes. If your hot query filters on two columns, you probably need an index designed for that access pattern, and you must validate with the database execution plan, not assumptions.
🌐 Step 8: Outbound HTTP and dependency calls
Outbound HTTP calls often dominate latency and create tail spikes.
Join the conversation! Your thoughts help the community grow.