
Implementing Human Memory Architectures in Metacognitive AI Systems
Abstract
Current large language model deployments operate with a profoundly impoverished memory architecture: a single, volatile context window that is discarded at session termination, coupled with a static parametric knowledge store that cannot be updated without full or parameter-efficient fine-tuning cycles. This architectural poverty is not a peripheral limitation. It is the root cause of the stateless epistemics, hallucination susceptibility, and absence of cumulative learning that define the intelligence gap in contemporary AI systems.
Cognitive neuroscience has long established that human intelligence is not constituted by a single unified memory system, but by a taxonomy of functionally distinct, neurologically dissociable memory subsystems — each encoding different categories of information, operating on different temporal horizons, and governed by different consolidation and retrieval mechanisms. The seven primary memory types identified in the cognitive science literature — Episodic, Semantic, Procedural, Working, Sensory, Short-Term, and Prospective — together constitute an integrated cognitive architecture whose collective properties give rise to the adaptive, self-correcting, context-sensitive intelligence that current AI systems approximate but do not replicate.
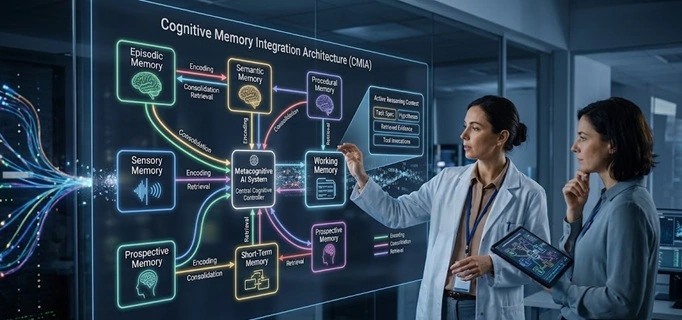
This paper provides a formally grounded, technically precise engineering blueprint for implementing each of these seven memory subsystems within a Metacognitive AI architecture. For each memory type, we establish: (1) the formal cognitive science characterization and its computational analogues; (2) the specific architectural components and data structures required for implementation; (3) the encoding, consolidation, and retrieval mechanisms appropriate to each type; (4) the integration interfaces through which each subsystem communicates with the central cognitive controller and with other memory subsystems; and (5) the governance and consistency mechanisms required for enterprise-grade deployment. The paper concludes with a unified Cognitive Memory Integration Architecture (CMIA) that synthesizes all seven subsystems into a coherent, metacognitively governed memory fabric.
1. Introduction: The Memory Gap in Contemporary AI
1.1 From Stateless Prediction to Stateful Cognition
The transformer architecture that underlies all contemporary frontier AI models encodes world knowledge in its parameters through the pretraining process and processes task-specific information through its context window during inference. This design yields a system with two fundamentally incompatible memory properties: near-unlimited parametric capacity (parameters encode a compressed statistical model of the entire training corpus) paired with zero persistent episodic capacity (nothing from one inference session is available to the next unless explicitly re-injected into the context).
This architectural configuration is, in cognitive terms, analogous to a human being who retains general semantic knowledge — language, facts, procedural skills — but is incapable of forming any new episodic memories and loses all working memory contents at the end of each waking period. Such an individual would exhibit apparent competence on isolated tasks but would be incapable of learning from experience, building on prior work, maintaining commitments across time, or developing the kind of contextually grounded judgment that constitutes expertise. This is, formally, the operational profile of every deployed LLM in production today.
1.2 Cognitive Neuroscience as Architectural Blueprint
The solution is not to build larger context windows, though extended context is a useful engineering palliative. The solution is to implement a multi-tier memory architecture that mirrors the functional organization of human memory as established by decades of cognitive neuroscience research. The seminal work of Tulving (1972, 1983) established the episodic/semantic distinction as a foundational taxonomy of long-term explicit memory. Subsequent work by Baddeley and Hitch (1974) formalized the multi-component model of working memory. Squire (1992) established the procedural/declarative taxonomy of long-term memory systems. Together, these frameworks provide a cognitively grounded blueprint for AI memory architecture that goes substantially beyond the ad hoc RAG pipelines and conversation-history prepending that constitute the current industry standard.
The following sections translate each cognitive memory type into a precise engineering specification, grounding each implementation in both its cognitive science rationale and its technical architecture. Throughout, we maintain alignment with the GSCP-15 metacognitive framework (Gödel, 2025), which provides the governing discipline within which these memory subsystems operate — determining what is encoded, when retrieval is triggered, how evidence is weighted, and how memory contents are validated and revised.
2. Working Memory: The Active Cognitive Workspace
2.1 Cognitive Science Characterization
Baddeley and Hitch's (1974) multi-component model characterizes Working Memory as the active cognitive workspace responsible for temporarily holding and manipulating information during complex cognitive tasks. It is not a passive storage buffer but an executive processing system comprising four components: the Central Executive (an attentional controller that coordinates the other components and manages cognitive resources), the Phonological Loop (processing verbal and auditory information), the Visuospatial Sketchpad (processing visual and spatial information), and the Episodic Buffer (integrating information from the other components and from long-term memory into a coherent episodic representation).
Critically, working memory is characterized by limited capacity (Miller's Law: 7±2 chunks; Cowan's revised estimate: 4±1), active maintenance (information decays rapidly without active rehearsal), and executive control (the central executive monitors contents, manages interference, and initiates retrieval from long-term memory). These properties are not incidental; they are the functional constraints that make working memory a focused, high-bandwidth cognitive workspace rather than a passive information dump.
2.2 Implementation Architecture
In a Metacognitive AI system, Working Memory is implemented as the Active Reasoning Context — a structured, capacity-constrained, actively managed data structure that holds the current task specification, intermediate reasoning states, active hypotheses, retrieved evidence fragments, and pending tool invocations within a single agentic reasoning cycle.
from dataclasses import dataclass, field
from typing import Any
from collections import deque
import time

@dataclass
class WorkingMemoryChunk:
    chunk_id: str
    content: Any
    modality: str          # 'verbal', 'spatial', 'episodic_buffer'
    salience_score: float  # executive attention weighting
    activation_level: float
    last_accessed: float   # Unix timestamp
    decay_rate: float      # exponential decay constant

class WorkingMemoryBuffer:
    """
    Implements a capacity-constrained, decay-governed active
    reasoning workspace with executive attention control.
    Capacity: 4-7 chunks (cognitively grounded constraint).
    """
    CAPACITY = 5  # Cowan's revised estimate

    def __init__(self):
        self.chunks: deque[WorkingMemoryChunk] = deque(maxlen=self.CAPACITY)
        self.central_executive = CentralExecutive()

    def encode(self, content: Any, modality: str, salience: float) -> str:
        """
        Encode a new chunk into working memory.
        If at capacity, displacement occurs via salience competition.
        """
        chunk = WorkingMemoryChunk(
            chunk_id=self._generate_id(),
            content=content,
            modality=modality,
            salience_score=salience,
            activation_level=1.0,
            last_accessed=time.time(),
            decay_rate=0.05  # ~20s half-life at 1Hz tick
        )
        if len(self.chunks) == self.CAPACITY:
            self._displace_by_salience(chunk)
        else:
            self.chunks.append(chunk)
        return chunk.chunk_id

    def rehearse(self, chunk_id: str) -> None:
        """Active rehearsal resets activation level to 1.0."""
        for chunk in self.chunks:
            if chunk.chunk_id == chunk_id:
                chunk.activation_level = 1.0
                chunk.last_accessed = time.time()
                return

    def tick_decay(self) -> None:
        """Apply exponential activation decay. Remove sub-threshold chunks."""
        elapsed = time.time()
        surviving = deque()
        for chunk in self.chunks:
            dt = elapsed - chunk.last_accessed
            chunk.activation_level *= (1 - chunk.decay_rate) ** dt
            if chunk.activation_level > 0.1:  # activation threshold
                surviving.append(chunk)
        self.chunks = surviving

    def get_active_context(self) -> list[WorkingMemoryChunk]:
        """Return all chunks above activation threshold, sorted by salience."""
        self.tick_decay()
        return sorted(self.chunks, key=lambda c: c.salience_score, reverse=True)

    def _displace_by_salience(self, incoming: WorkingMemoryChunk):
        """Displace lowest-salience chunk to admit higher-salience incoming."""
        if self.chunks:
            lowest = min(self.chunks, key=lambda c: c.salience_score)
            if incoming.salience_score > lowest.salience_score:
                self.chunks.remove(lowest)
                self.chunks.append(incoming)
2.3 Central Executive Implementation
The Central Executive component — the attentional controller of working memory — maps directly onto the metacognitive orchestrator of a GSCP-15-governed system: the component that monitors active reasoning quality, allocates computational resources across concurrent reasoning branches, detects interference between competing hypotheses, and initiates retrieval from long-term memory subsystems when working memory content is insufficient.
class CentralExecutive:
    """
    Metacognitive controller for working memory. Monitors
    reasoning quality, manages resource allocation, and
    triggers long-term memory retrieval when needed.
    """
    def evaluate_reasoning_quality(
        self,
        wm: WorkingMemoryBuffer,
        current_hypothesis: str
    ) -> ReasoningQualityReport:
        active = wm.get_active_context()
        return ReasoningQualityReport(
            coherence_score=self._compute_coherence(active, current_hypothesis),
            evidence_adequacy=self._assess_evidence_coverage(active),
            uncertainty_flags=self._identify_unsupported_claims(active),
            retrieval_triggers=self._determine_retrieval_needs(active)
        )

    def _determine_retrieval_needs(
        self,
        chunks: list[WorkingMemoryChunk]
    ) -> list[RetrievalTrigger]:
        """
        Identify gaps in working memory content that require
        retrieval from episodic, semantic, or procedural stores.
        """
        triggers = []
        for chunk in chunks:
            if chunk.activation_level < 0.4 and chunk.salience_score > 0.7:
                triggers.append(RetrievalTrigger(
                    target_store='episodic' if chunk.modality == 'episodic_buffer'
                                 else 'semantic',
                    query_content=chunk.content,
                    urgency=chunk.salience_score
                ))
        return triggers
3. Sensory Memory: The Perceptual Gateway
3.1 Cognitive Science Characterization
Sensory Memory is the earliest and most transient stage of memory processing, representing the immediate, pre-attentive registration of sensory input before any cognitive processing has occurred. Sperling's (1960) landmark experiments established the iconic store (visual sensory memory) as holding a high-fidelity, complete representation of a visual scene for approximately 250–500 milliseconds, with an effective capacity approximating the full visual field. The echoic store (auditory sensory memory) retains a verbatim trace of auditory input for 3–4 seconds. The functional role of sensory memory is selective attention gating: the attentional system scans the high-capacity sensory buffer and selectively transfers salient items to working memory before they decay.
3.2 Implementation Architecture
In an AI system processing multimodal inputs — text streams, document uploads, image inputs, audio transcripts, real-time data feeds — Sensory Memory is implemented as a high-capacity, short-retention input buffer with an attention-based salience filter that governs which input elements are selected for transfer to working memory and encoding into longer-term stores.
import asyncio
from dataclasses import dataclass
from typing import Callable
import numpy as np

@dataclass
class SensoryTrace:
    trace_id: str
    raw_content: bytes | str
    modality: str          # 'visual', 'auditory', 'textual', 'structured'
    timestamp: float
    ttl_ms: int            # time-to-live in milliseconds
    salience_score: float  # computed by salience filter

class SensoryBuffer:
    """
    High-capacity, rapidly-decaying perceptual input buffer.
    TTL: 200-500ms for visual, 3000-4000ms for auditory/textual.
    Implements attention-gated transfer to working memory.
    """
    TTL_BY_MODALITY = {
        'visual': 400,       # ms — iconic store duration
        'auditory': 3500,    # ms — echoic store duration
        'textual': 3000,
        'structured': 5000   # data streams: slightly extended
    }

    def __init__(self, salience_model: Callable, wm: WorkingMemoryBuffer):
        self.buffer: list[SensoryTrace] = []
        self.salience_model = salience_model
        self.working_memory = wm
        self._sweep_task = None

    async def ingest(self, raw_input: bytes | str, modality: str) -> None:
        """Receive a new sensory input and compute its salience."""
        salience = await self.salience_model(raw_input, modality)
        trace = SensoryTrace(
            trace_id=self._generate_id(),
            raw_content=raw_input,
            modality=modality,
            timestamp=time.time(),
            ttl_ms=self.TTL_BY_MODALITY.get(modality, 3000),
            salience_score=salience
        )
        self.buffer.append(trace)
        if salience > 0.75:  # high-salience items trigger immediate transfer
            await self._transfer_to_working_memory(trace)

    async def attention_sweep(self, interval_ms: int = 100) -> None:
        """
        Periodic sweep: expire decayed traces, transfer salient
        survivors to working memory, log discarded traces for audit.
        """
        while True:
            now = time.time()
            surviving, expired = [], []
            for trace in self.buffer:
                age_ms = (now - trace.timestamp) * 1000
                if age_ms < trace.ttl_ms:
                    surviving.append(trace)
                else:
                    expired.append(trace)

            # Transfer surviving high-salience items to WM
            for trace in surviving:
                if trace.salience_score > 0.5:
                    await self._transfer_to_working_memory(trace)

            # Audit log discarded traces (governance requirement)
            for trace in expired:
                await self._audit_log_expiry(trace)

            self.buffer = surviving
            await asyncio.sleep(interval_ms / 1000)

    async def _transfer_to_working_memory(self, trace: SensoryTrace) -> None:
        processed = await self._preprocess(trace)
        self.working_memory.encode(
            content=processed,
            modality=trace.modality,
            salience=trace.salience_score
        )
4. Short-Term Memory: The Consolidation Antechamber
4.1 Cognitive Science Characterization
Short-Term Memory (STM) — distinct from working memory in classical models, though often conflated in popular usage — refers to the passive retention of small amounts of information for intervals of approximately 15–30 seconds in the absence of active rehearsal. The seminal work of Peterson and Peterson (1959) demonstrated that unrehearsed verbal information decays from short-term store to near-zero recall within approximately 18 seconds, establishing the characteristic temporal decay function that distinguishes STM from long-term consolidation. STM capacity is typically characterized as 7±2 items (Miller, 1956), though subsequent research suggests that chunking — the aggregation of items into meaningful units — substantially modulates effective capacity.
The functional role of STM in the broader memory architecture is that of consolidation antechamber: information that has passed the attentional filter from sensory memory and is being actively processed in working memory may, through rehearsal and consolidation processes, be transferred to long-term episodic or semantic stores. STM is the temporal bridge across which this consolidation occurs.
4.2 Implementation Architecture
In an AI system, Short-Term Memory is implemented as a session-scoped, time-indexed interaction log with a configurable retention window, automatic chunking and compression, and selective consolidation routing to long-term stores based on novelty, utility, and relevance scoring.
import hashlib
from datetime import datetime, timedelta
from typing import Optional
import redis  # Redis for fast time-indexed session store

class ShortTermMemoryStore:
    """
    Session-scoped interaction log with TTL-governed retention
    and selective consolidation to long-term episodic/semantic stores.
    Backed by Redis for millisecond-latency access.
    Retention window: configurable, default 30 minutes (extended STM for AI).
    """
    DEFAULT_TTL_SECONDS = 1800  # 30 minutes

    def __init__(
        self,
        session_id: str,
        redis_client: redis.Redis,
        consolidation_router: 'ConsolidationRouter'
    ):
        self.session_id = session_id
        self.redis = redis_client
        self.router = consolidation_router
        self.namespace = f"stm:{session_id}"

    def encode(
        self,
        content: dict,
        ttl: int = DEFAULT_TTL_SECONDS,
        consolidation_priority: float = 0.5
    ) -> str:
        """
        Encode a new item into STM with TTL and consolidation metadata.
        """
        item_id = self._generate_id()
        entry = {
            'item_id': item_id,
            'content': content,
            'encoded_at': datetime.utcnow().isoformat(),
            'consolidation_priority': consolidation_priority,
            'access_count': 0,
            'chunk_signature': self._compute_chunk_hash(content)
        }
        key = f"{self.namespace}:{item_id}"
        self.redis.setex(key, ttl, json.dumps(entry))
        return item_id

    def retrieve(self, item_id: str) -> Optional[dict]:
        """Retrieve item and increment access count (rehearsal effect)."""
        key = f"{self.namespace}:{item_id}"
        raw = self.redis.get(key)
        if not raw:
            return None
        entry = json.loads(raw)
        entry['access_count'] += 1
        # Rehearsal: extend TTL proportional to access frequency
        new_ttl = self.DEFAULT_TTL_SECONDS + (entry['access_count'] * 120)
        self.redis.setex(key, min(new_ttl, 7200), json.dumps(entry))
        return entry

    def get_session_contents(self) -> list[dict]:
        """Return all active STM items for the current session."""
        pattern = f"{self.namespace}:*"
        keys = self.redis.keys(pattern)
        items = []
        for key in keys:
            raw = self.redis.get(key)
            if raw:
                items.append(json.loads(raw))
        return sorted(items, key=lambda x: x['encoded_at'])

    async def consolidation_sweep(self) -> ConsolidationReport:
        """
        Identify high-priority items for consolidation to long-term stores.
        Consolidation criteria: high access count OR high priority score.
        """
        items = self.get_session_contents()
        candidates = [
            item for item in items
            if item['consolidation_priority'] > 0.7
            or item['access_count'] >= 3
        ]
        return await self.router.route_for_consolidation(candidates)

    def _compute_chunk_hash(self, content: dict) -> str:
        """Deduplication signature to prevent redundant encoding."""
        canonical = json.dumps(content, sort_keys=True)
        return hashlib.sha256(canonical.encode()).hexdigest()[:16]
5. Episodic Memory: Autobiographical Experience and Contextual Recall
5.1 Cognitive Science Characterization
Episodic Memory, introduced by Tulving (1972) and extensively elaborated in his subsequent work (1983, 2002), is the memory system that stores and retrieves specific personal experiences and events, bound to their spatiotemporal context. Episodic memories are characterized by what Tulving terms "mental time travel": the capacity to consciously re-experience a past event, reconstructing not merely the factual content of the experience but its contextual embedding — when it occurred, where, in what circumstances, with what emotional valence, and in what relation to other events. The neural substrate of episodic memory is centered on the hippocampus, which acts as a relational binding system, associating disparate elements of an experience (perceptual details, temporal context, spatial context, emotional state) into a coherent, retrievable memory trace.
Episodic memory is fundamentally reconstructive rather than reproductive: retrieval does not access a stored recording of an event but actively reconstructs it from constituent traces, a process that is context-sensitive, subject to interference, and susceptible to updating by post-event information. This reconstructive property has critical implications for AI implementation: an episodic memory system must implement not merely storage and retrieval but consistency maintenance across the network of related memories.
5.2 Implementation Architecture: Vector-Indexed Experience Store
In a Metacognitive AI system, Episodic Memory is implemented as a persistently indexed, contextually richly annotated experience store built on a vector database with dense semantic embeddings enabling similarity-based retrieval. Critically, each episodic trace encodes not merely the content of an interaction but its full contextual envelope: temporal context, task context, agent state, confidence levels, tool invocations, intermediate reasoning steps, and outcome quality assessment.
from dataclasses import dataclass, field
from typing import Optional
import numpy as np
import faiss  # Facebook AI Similarity Search for ANN retrieval
from sentence_transformers import SentenceTransformer

@dataclass
class EpisodicTrace:
    """
    A richly annotated record of a specific AI reasoning episode.
    Implements Tulving's 'what-where-when' episodic binding.
    """
    # Identity
    trace_id: str
    session_id: str
    agent_id: str

    # Content (the "what")
    task_specification: str
    reasoning_trajectory: list[dict]  # full chain-of-thought record
    tool_invocations: list[dict]
    retrieved_evidence: list[str]
    final_output: str

    # Context (the "where" and "when")
    timestamp_start: float
    timestamp_end: float
    domain_context: str
    user_intent_classification: str

    # Quality metadata (for consolidation priority scoring)
    outcome_quality_score: float    # 0.0–1.0
    user_feedback_signal: Optional[float]
    confidence_at_output: float
    hallucination_flags: list[str]  # detected uncertain assertions

    # Relational bindings (links to related episodes)
    related_trace_ids: list[str] = field(default_factory=list)
    semantic_cluster_id: Optional[str] = None

    # Embedding (computed at encoding time)
    embedding: Optional[np.ndarray] = None


class EpisodicMemoryStore:
    """
    Persistently indexed episodic memory with:
    - Dense vector indexing (FAISS HNSW) for similarity retrieval
    - Contextual filtering (temporal, domain, quality)
    - Reconstructive retrieval with related-trace augmentation
    - Hippocampal binding simulation via relational graph
    """
    EMBEDDING_DIM = 1536  # text-embedding-3-large dimensionality

    def __init__(self, db_connection, embedding_model: SentenceTransformer):
        self.db = db_connection
        self.embedder = embedding_model
        self.index = faiss.IndexHNSWFlat(self.EMBEDDING_DIM, 32)
        # HNSW: M=32 neighbors, ef_construction=200 for high-recall indexing
        self.index.hnsw.efConstruction = 200
        self.index.hnsw.efSearch = 64
        self.id_map: dict[int, str] = {}  # FAISS int → trace_id mapping

    def encode(self, trace: EpisodicTrace) -> str:
        """
        Encode a new episodic trace.
        1. Generate dense embedding of the full contextual representation.
        2. Index in FAISS for similarity retrieval.
        3. Persist full trace to document store.
        4. Update relational binding graph.
        """
        # Construct rich text representation for embedding
        embedding_input = self._build_embedding_representation(trace)
        trace.embedding = self.embedder.encode(
            embedding_input, normalize_embeddings=True
        )

        # FAISS indexing
        faiss_id = len(self.id_map)
        self.index.add(trace.embedding.reshape(1, -1))
        self.id_map[faiss_id] = trace.trace_id

        # Persistent storage
        self.db.episodic_traces.insert_one(self._serialize(trace))

        # Update relational bindings
        self._update_relational_graph(trace)
        return trace.trace_id

    def retrieve(
        self,
        query: str,
        k: int = 5,
        domain_filter: Optional[str] = None,
        min_quality_score: float = 0.3,
        temporal_window_days: Optional[int] = None
    ) -> list[EpisodicTrace]:
        """
        Similarity-based retrieval with contextual filtering.
        Implements reconstructive retrieval: augments top-k results
        with relationally bound traces for context completeness.
        """
        query_embedding = self.embedder.encode(
            query, normalize_embeddings=True
        ).reshape(1, -1)

        # ANN search — returns candidate pool larger than k for post-filtering
        distances, faiss_ids = self.index.search(query_embedding, k * 3)
        candidates = []
        for dist, fid in zip(distances[0], faiss_ids[0]):
            if fid == -1:
                continue
            trace_id = self.id_map.get(int(fid))
            trace = self._fetch_trace(trace_id)
            if trace and self._passes_filters(
                trace, domain_filter, min_quality_score, temporal_window_days
            ):
                candidates.append((float(dist), trace))

        # Sort by similarity, take top-k
        candidates.sort(key=lambda x: x[0], reverse=True)
        primary_results = [t for _, t in candidates[:k]]

        # Reconstructive augmentation: retrieve relationally bound traces
        augmented = self._reconstruct_with_related(primary_results)
        return augmented

    def _build_embedding_representation(self, trace: EpisodicTrace) -> str:
        """
        Construct a rich textual representation encoding all
        contextual dimensions for multi-aspect similarity retrieval.
        """
        return (
            f"Task: {trace.task_specification}\n"
            f"Domain: {trace.domain_context}\n"
            f"Intent: {trace.user_intent_classification}\n"
            f"Output: {trace.final_output}\n"
            f"Quality: {trace.outcome_quality_score:.2f}\n"
            f"Reasoning: {' '.join([s['thought'] for s in trace.reasoning_trajectory[:3]])}"
        )

    def _update_relational_graph(self, trace: EpisodicTrace) -> None:
        """
        Identify and record relational bindings to existing traces.
        Implements hippocampal binding: associates episodes sharing
        domain context, task type, or output patterns.
        """
        similar = self.retrieve(
            trace.task_specification, k=3, min_quality_score=0.0
        )
        for related in similar:
            if related.trace_id != trace.trace_id:
                trace.related_trace_ids.append(related.trace_id)
                # Bidirectional binding
                self.db.episodic_traces.update_one(
                    {'trace_id': related.trace_id},
                    {'$addToSet': {'related_trace_ids': trace.trace_id}}
                )
Join the conversation! Your thoughts help the community grow.