
Artificial Intelligence (AI) has been a fascinating concept of science fiction for decades, but many researchers think we’re finally getting close to making AI a reality. Google CEO Sundar Pichai noted during his keynote segment in Google I/O that the company is moving from being a mobile first company to an AI first one. Microsoft is essentially on the same path, even as its CEO Satya Nadella phrased it differently.
Machine learning is the modern science of finding patterns and making predictions from data based on different situations. Some argue it's same as AI but it's not it's not but it's proving to be most successful approach to the AI.
The world is being reshaped by machine learning and we no longer need to teach computers how to perform complex tasks. To stay ahead, we should learn to build systems that let them learn how to do it themselves.
AZURE ML Studio is a recognized game changer in applying the power of the cloud to solve the problem of big data processing. It offers a simple and intuitive framework to develop machine learning and Data Science applications, and has an easy to use graphical interface that allows you to quickly develop machine learning apps.This is more of a big picture way of putting an entire simple machine learning pipeline together without having to actually write any code. Moreover, it empowers "normal" developers to approach the world of data science without a deep mathematical background, which actually makes the whole process easier even for experienced programmers.
The topic is divided into two articles. First part will explain how to import a data set into Azure ML Studio and use that to create an experiment that will be used to publish as a web service.
Prerequisites
- AZURE ML account
- Visual Studio
Let's get started.
- Open Azure ML Studio and sign in using your Azure ML account.
- Select the Datasets icon on the left nav bar of Azure ML Studio home page.
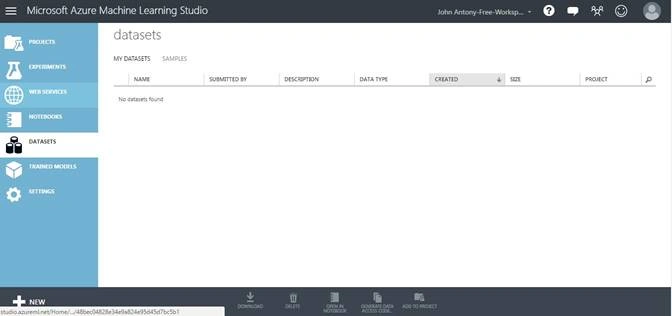
- Click "New" on lower left corner to upload the dataset. Choose dataset and then select "From Local File". Locate the file that you had just downloaded and upload it by selecting the tick mark on the lower right corner.
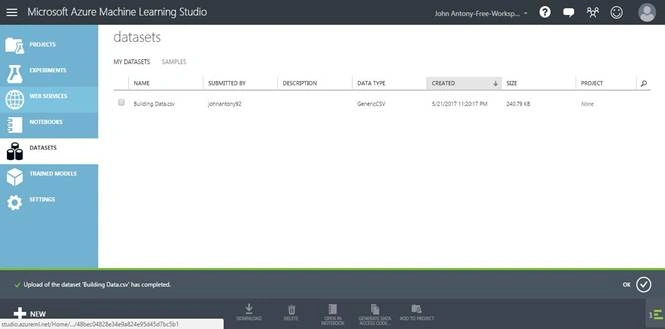
- Next, click on "Experiments" on the nav bar and select "Blank Experiment".
- Expand the Dataset folder and drag and drop the data set that we had just added (here ‘Building.csv’’).
- Expand the data transformation category and drag and drop ‘Split Data’ into the designer surface. Split data is used to divide data into two sets mostly used when you need to split the data into training and testing sets.
- Also, set a fraction of rows in the first output dataset to 0.7 to split the data at 70/30 i.e 70% for training and 30% for testing.
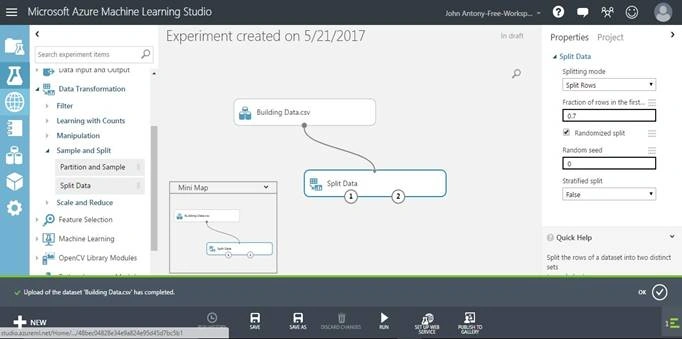
- Expand the Machine Learning category, then Initialize Model, and finally Regression. Locate the "Decision Forest Regression" entry and drag it onto the designer surface. Also, drag and drop Score Model from Score subcategory, Train Model from Train category, and the Evaluate Model from Evaluate subcateogry. Now, the designer window should look like the one shown in fig.
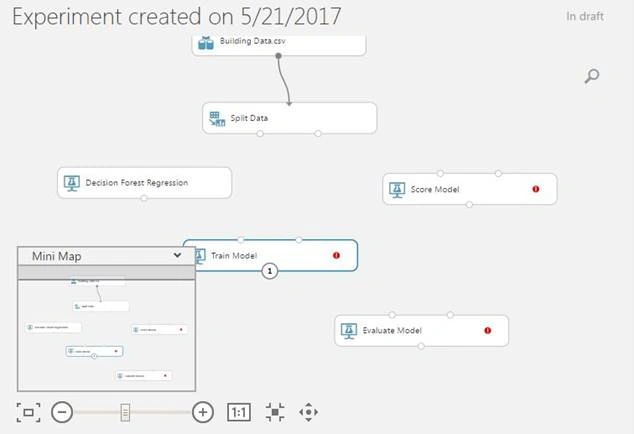
Decision Forest Regression
This is used to create a regression model (regression analysis is a statical process of estimating relationship among the variales.It is done traversing and analysing sets of data where the focus is on dependent and independent variables) using a collection of decision trees. After you configure the model, you must train it using Train model.
Join the conversation! Your thoughts help the community grow.