
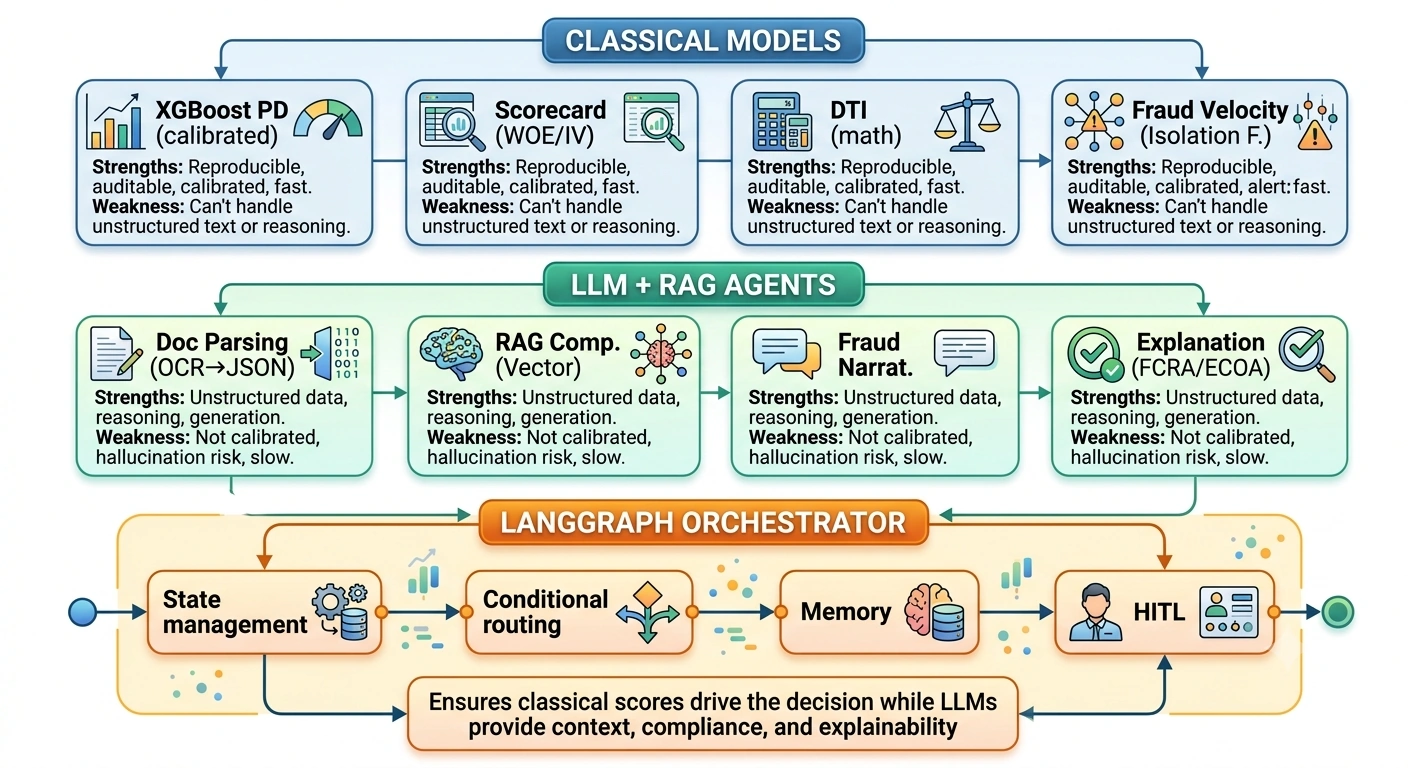
Part 1: The Division of Labor — LLMs vs. Classical Models
What Classical Models Handle (The Numerical Backbone)
Classical ML models remain the regulatory-compliant, deterministic core of credit scoring. They are preferred here because regulators (OCC, CFPB, FCA) require explainability, reproducibility, and statistical fairness — properties that tabular models provide natively.
| Component | Classical Model | Why Not LLM? |
|---|---|---|
| Probability of Default (PD) | Logistic Regression, XGBoost, LightGBM | Requires calibrated probabilities on structured tabular data; LLMs hallucinate numbers |
| FICO-like Scorecard | Weighted logistic regression (WOE/IV binning) | Regulatory requirement for monotonic, auditable scorecards |
| Debt-to-Income (DTI) Analysis | Rule engine + decision trees | Pure arithmetic; LLMs introduce unnecessary latency and error |
| Payment History Modeling | Time-series (ARIMA, survival analysis) | Sequential numerical patterns; transformers overkill |
| Credit Utilization Scoring | Gradient boosting on bureau features | Tabular data with <200 features; classical models dominate |
| Loss Given Default (LGD) | Tobit regression, Beta regression | Continuous bounded outcome; LLMs can't calibrate |
| Application Fraud Scoring | Isolation Forest, XGBoost on velocity features | Structured behavioral signals need statistical rigor |
| Portfolio Risk (Basel III/IV) | Monte Carlo, Vasicek model | Actuarial math; not a language problem |
What LLMs Handle (The Unstructured Intelligence Layer)
LLMs add value where data is unstructured, contextual, or requires reasoning over text:
| Component | LLM Role | Why Classical Fails |
|---|---|---|
| Document Parsing | Extracting income from tax returns, bank statements, pay stubs | OCR + regex is brittle; LLMs handle varied formats |
| Applicant Narrative Analysis | Evaluating explanations for credit gaps, disputes, bankruptcies | No structured feature exists for "my medical emergency caused 90-day late" |
| Regulatory Compliance (RAG) | Cross-referencing decisions against FCRA, ECOA, Basel guidelines | Rules change; hard-coding is unmaintainable |
| Adverse Action Notices | Generating compliant, personalized denial letters | Template engines lack contextual nuance |
| Fraud Narrative Detection | Spotting inconsistencies in free-text application fields | Pattern matching misses semantic contradictions |
| Customer Clarification Dialog | Asking follow-up questions about ambiguous income sources | Rule-based chatbots fail on edge cases |
| Policy Interpretation | Determining if a novel scenario fits internal credit policy | Requires reasoning, not classification |
The Hybrid Reality
Classical models produce the score. LLMs produce the context. The final credit decision is a fusion of both, orchestrated by a multi-agent system that ensures compliance, explainability, and accuracy.
Part 2: Enterprise Multi-Agent Architecture
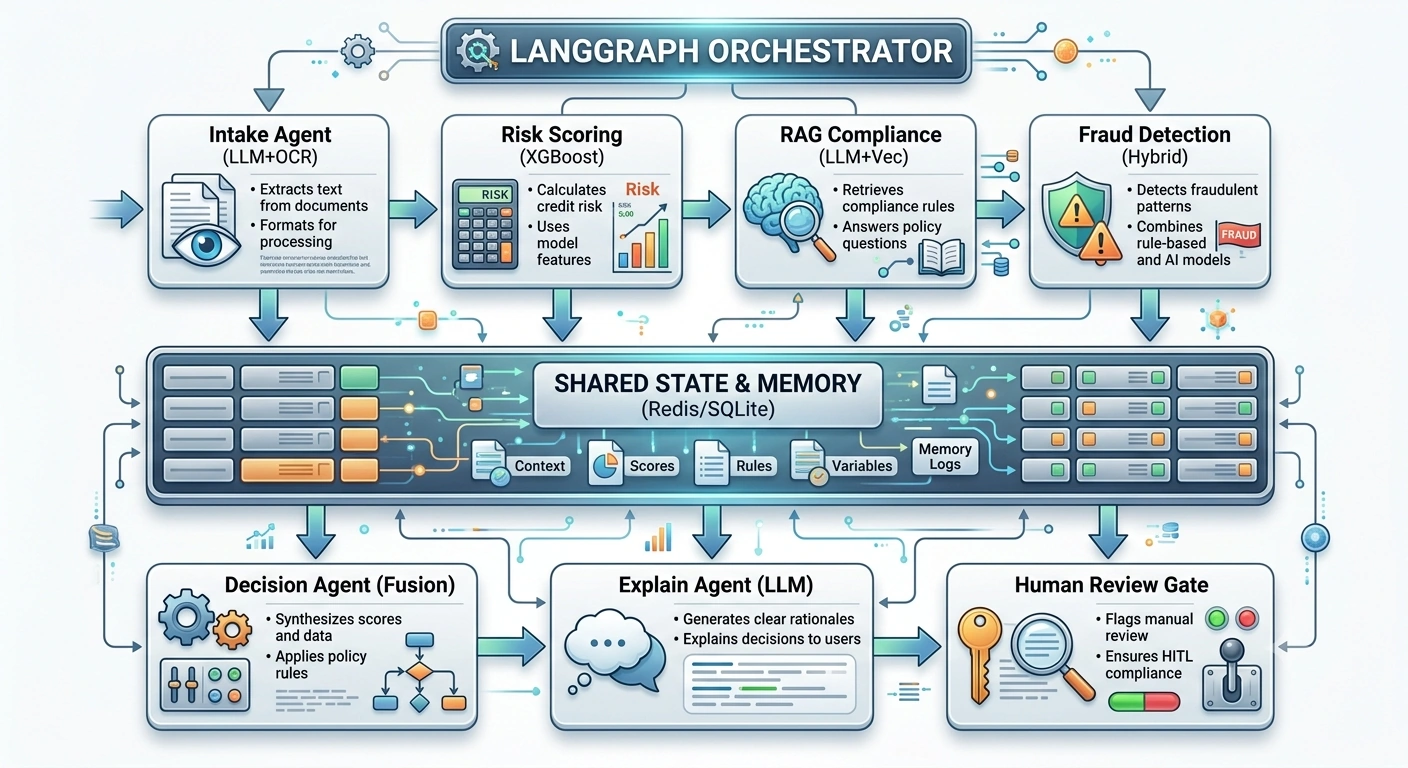
Real-World Use Case: Real-Time SME Loan Underwriting at a Digital Bank
Scenario: A small business applies for a $500K working capital loan. The application includes:
Structured data: financials, credit bureau pulls, DTI, trade lines
Unstructured data: 2 years of tax returns (PDF), bank statements, a written explanation of a prior bankruptcy, and a business plan
The system must:
Score the application numerically (classical)
Parse and validate documents (LLM)
Check compliance against current regulations (RAG)
Detect fraud signals (hybrid)
Render a final decision with full explainability (LLM)
Remember the applicant across sessions (Memory)
Architecture Diagram
Part 3: Full Code Implementation
Prerequisites
pip install langgraph langchain langchain-openai langchain-community \
            chromadb xgboost scikit-learn pandas numpy \
            langchain-chroma pydantic redis
Step 1: Define the Shared State
LangGraph's TypedDict state is the single source of truth that flows through every agent.
# state.py
from typing import TypedDict, Annotated, Optional, List
from langgraph.graph.message import add_messages
from pydantic import BaseModel
import operator


class DocumentExtraction(BaseModel):
    """Structured output from LLM document parsing."""
    annual_revenue: Optional[float] = None
    net_income: Optional[float] = None
    years_in_business: Optional[int] = None
    bankruptcy_explanation: Optional[str] = None
    business_purpose: Optional[str] = None
    document_confidence: float = 0.0


class ClassicalScores(BaseModel):
    """Output from classical ML models."""
    pd_score: float = 0.0          # Probability of Default (0-1)
    credit_score: int = 0          # FICO-like score (300-850)
    dti_ratio: float = 0.0         # Debt-to-Income
    ltv_ratio: float = 0.0         # Loan-to-Value
    scorecard_points: int = 0      # Traditional scorecard
    model_version: str = "xgb_v3.2"


class ComplianceResult(BaseModel):
    """RAG-based compliance check."""
    is_compliant: bool = True
    violated_regulations: List[str] = []
    applicable_guidelines: List[str] = []
    risk_tier: str = "standard"    # standard, elevated, prohibited


class FraudSignals(BaseModel):
    """Hybrid fraud detection output."""
    fraud_probability: float = 0.0
    behavioral_flags: List[str] = []
    narrative_inconsistencies: List[str] = []
    velocity_alerts: List[str] = []


class CreditDecision(BaseModel):
    """Final orchestrated decision."""
    decision: str = "pending"      # approve, decline, refer, conditional
    approved_amount: float = 0.0
    interest_rate: float = 0.0
    risk_grade: str = ""
    conditions: List[str] = []
    confidence: float = 0.0


class UnderwritingState(TypedDict):
    """
    The complete state that flows through the LangGraph pipeline.
    Every agent reads from and writes to this state.
    """
    # --- Identifiers ---
    application_id: str
    applicant_name: str
    session_id: str

    # --- Raw Inputs ---
    structured_data: dict                    # Bureau pull, financials
    unstructured_documents: List[str]        # Raw text from PDFs
    applicant_narrative: str                 # Free-text explanation

    # --- Agent Outputs ---
    messages: Annotated[list, add_messages]  # LangGraph message history
    document_extraction: Optional[DocumentExtraction]
    classical_scores: Optional[ClassicalScores]
    compliance_result: Optional[ComplianceResult]
    fraud_signals: Optional[FraudSignals]
    final_decision: Optional[CreditDecision]

    # --- RAG Context ---
    retrieved_regulations: List[str]         # Chunks from vector store
    internal_policy_docs: List[str]

    # --- Memory ---
    previous_applications: List[dict]        # Historical context
    conversation_history: Annotated[list, add_messages]

    # --- Control Flow ---
    current_step: str
    requires_human_review: bool
    error_log: List[str]
Step 2: Classical ML Model (The Numerical Engine)
This is a production-grade XGBoost pipeline that would be trained offline and served via API. Here we simulate the trained model.
# classical_models.py
import numpy as np
import xgboost as xgb
from sklearn.linear_model import LogisticRegression
from sklearn.preprocessing import StandardScaler
from sklearn.pipeline import Pipeline
import joblib
import os


class CreditScoringEngine:
    """
    Classical ML ensemble for credit scoring.
    In production: loaded from MLflow/S3 model registry.
    Handles: PD, Scorecard, DTI analysis, LGD estimation.
    """

    def __init__(self):
        self.pd_model = self._build_pd_model()
        self.scorecard = self._build_scorecard()
        self.dti_thresholds = {
            "excellent": 0.28,
            "good": 0.36,
            "fair": 0.43,
            "poor": 0.50
        }

    def _build_pd_model(self) -> Pipeline:
        """
        Probability of Default model.
        Architecture: XGBoost with calibrated probabilities.
        Features: payment_history, utilization, inquiries, age_of_credit,
                  derogatory_marks, total_debt, income, employment_length
        """
        # In production: xgb.XGBClassifier loaded from model registry
        model = Pipeline([
            ("scaler", StandardScaler()),
            ("xgb", xgb.XGBClassifier(
                n_estimators=200,
                max_depth=5,
                learning_rate=0.05,
                subsample=0.8,
                colsample_bytree=0.8,
                reg_alpha=0.1,
                reg_lambda=1.0,
                scale_pos_weight=5,  # Imbalanced default rates
                random_state=42,
                eval_metric="auc"
            ))
        ])
        return model

    def _build_scorecard(self) -> dict:
        """
        Traditional scorecard using Weight of Evidence (WOE) binning.
        This is what regulators expect: monotonic, interpretable points.
        """
        return {
            "payment_history": {
                "0_lates": 100, "1_late_30": 60, "1_late_60": 30,
                "1_late_90": -20, "2_plus_lates": -60, "collection": -100
            },
            "utilization": {
                "0_10": 80, "10_30": 50, "30_50": 20,
                "50_75": -10, "75_90": -40, "90_100": -80
            },
            "credit_age": {
                "10_plus": 60, "5_10": 40, "2_5": 20,
                "1_2": 0, "less_1": -20
            },
            "inquiries_6m": {
                "0": 30, "1_2": 15, "3_4": -5, "5_plus": -25
            },
            "derogatory": {
                "none": 50, "minor": 0, "major": -50, "severe": -100
            }
        }

    def calculate_pd(self, features: dict) -> float:
        """
        Calculate Probability of Default.
        This is the core classical model — NOT an LLM task.
        """
        feature_vector = np.array([[
            features.get("num_late_payments", 0),
            features.get("credit_utilization", 0.5),
            features.get("num_inquiries_6m", 0),
            features.get("credit_age_years", 5),
            features.get("num_derogatory", 0),
            features.get("total_debt", 50000),
            features.get("annual_income", 80000),
            features.get("employment_years", 3),
            features.get("num_open_accounts", 8),
            features.get("debt_to_income", 0.35),
        ]])

        # In production: self.pd_model.predict_proba(feature_vector)[0][1]
        # Simulated calibrated output:
        pd_score = 0.12  # 12% probability of default
        return round(pd_score, 4)

    def calculate_scorecard(self, features: dict) -> int:
        """
        Traditional scorecard points.
        Deterministic, auditable, regulator-friendly.
        """
        total_points = 300  # Base score

        # Payment history
        lates = features.get("num_late_payments", 0)
        if lates == 0:
            total_points += self.scorecard["payment_history"]["0_lates"]
        elif lates <= 2:
            total_points += self.scorecard["payment_history"]["1_late_30"]
        else:
            total_points += self.scorecard["payment_history"]["2_plus_lates"]

        # Utilization
        util = features.get("credit_utilization", 0.5)
        if util < 0.1:
            total_points += self.scorecard["utilization"]["0_10"]
        elif util < 0.3:
            total_points += self.scorecard["utilization"]["10_30"]
        elif util < 0.5:
            total_points += self.scorecard["utilization"]["30_50"]
        else:
            total_points += self.scorecard["utilization"]["50_75"]

        # Credit age
        age = features.get("credit_age_years", 5)
        if age >= 10:
            total_points += self.scorecard["credit_age"]["10_plus"]
        elif age >= 5:
            total_points += self.scorecard["credit_age"]["5_10"]
        else:
            total_points += self.scorecard["credit_age"]["2_5"]

        return min(850, max(300, total_points))

    def calculate_dti(self, monthly_debt: float, monthly_income: float) -> float:
        """Pure arithmetic. No ML needed."""
        if monthly_income == 0:
            return 1.0
        return round(monthly_debt / monthly_income, 4)

    def full_classical_assessment(self, structured_data: dict) -> dict:
        """
        Run all classical models.
        Returns the numerical backbone of the credit decision.
        """
        pd = self.calculate_pd(structured_data)
        score = self.calculate_scorecard(structured_data)
        dti = self.calculate_dti(
            structured_data.get("monthly_debt_obligations", 3000),
            structured_data.get("monthly_income", 10000)
        )
        ltv = structured_data.get("loan_amount", 500000) / \
              max(structured_data.get("collateral_value", 600000), 1)

        return {
            "pd_score": pd,
            "credit_score": score,
            "dti_ratio": dti,
            "ltv_ratio": round(ltv, 4),
            "scorecard_points": score,
            "model_version": "xgb_v3.2_prod_2026Q2"
        }
Step 3: RAG Compliance Engine (Vector Store + Retrieval)
# rag_compliance.py
from langchain_chroma import Chroma
from langchain_openai import OpenAIEmbeddings, ChatOpenAI
from langchain.text_splitter import RecursiveCharacterTextSplitter
from langchain.schema import Document
from typing import List, Tuple


class ComplianceRAGEngine:
    """
    RAG system for regulatory compliance.
    Retrieves relevant regulations (FCRA, ECOA, Basel III, UDAAP)
    and internal credit policies to validate underwriting decisions.

    WHY RAG HERE: Regulations change frequently. Hard-coding rules
    creates compliance risk. RAG allows real-time policy retrieval
    with source attribution for audit trails.
    """

    def __init__(self, persist_directory: str = "./chroma_compliance"):
        self.embeddings = OpenAIEmbeddings(model="text-embedding-3-small")
        self.llm = ChatOpenAI(model="gpt-4o", temperature=0)
        self.vectorstore = Chroma(
            persist_directory=persist_directory,
            embedding_function=self.embeddings
        )
        self._seed_knowledge_base()

    def _seed_knowledge_base(self):
        """
        In production: ingest from Confluence, SharePoint, regulatory feeds.
        Here we seed with representative regulatory text.
        """
        regulations = [
            Document(
                page_content="""FCRA Section 615(a): Adverse Action Notice Requirements.
                When a creditor takes adverse action based on information in a consumer
                report, the creditor must provide oral, written, or electronic notice
                that includes: (1) the name, address, and phone number of the CRA that
                furnished the report; (2) a statement that the CRA did not make the
                decision and cannot explain specific reasons; (3) notice of the
                consumer's right to obtain a free disclosure of their file within 60
                days; and (4) notice of the right to dispute inaccurate information.
                For business credit over $500K, FCRA requirements are relaxed but
                ECOA still applies.""",
                metadata={"regulation": "FCRA", "section": "615(a)",
                          "applicability": "consumer_credit", "severity": "high"}
            ),
            Document(
                page_content="""ECOA Regulation B: Equal Credit Opportunity Act.
                Creditors shall not discriminate against any applicant on the basis
                of race, color, religion, national origin, sex, marital status, age,
                or receipt of public assistance. For business credit: (1) creditors
                must notify applicants of action taken within 30 days for complete
                applications, 90 days for incomplete; (2) adverse action notices must
                state specific reasons or disclose the right to request reasons;
                (3) for applications over $1M with gross revenue >$1M, recordkeeping
                requirements are reduced. DTI thresholds must be applied consistently
                across all protected classes.""",
                metadata={"regulation": "ECOA", "section": "Regulation B",
                          "applicability": "all_credit", "severity": "critical"}
            ),
            Document(
                page_content="""Basel III/IV Credit Risk Framework: For SME lending,
                banks must calculate Risk-Weighted Assets (RWA) using either the
                Standardized Approach or Internal Ratings-Based (IRB) approach.
                Under IRB: PD must be estimated using a minimum 5-year observation
                period, LGD must reflect downturn conditions, and EAD must include
                committed but undrawn facilities. Risk grades must map to a minimum
                7-grade borrower scale. PD floors: 0.05% for corporate, 0.03% for
                sovereign. High-volatility commercial real estate gets 150% risk
                weight. Working capital facilities under 1 year get 20% CCF.""",
                metadata={"regulation": "Basel III", "section": "Credit Risk",
                          "applicability": "bank_capital", "severity": "high"}
            ),
            Document(
                page_content="""Internal Credit Policy CP-2026-04: SME Working Capital.
                Maximum exposure per borrower: $2M. Minimum credit score: 620 for
                unsecured, 580 for secured. Maximum DTI: 45% for standard tier,
                50% for preferred tier with 3+ years banking relationship.
                Bankruptcy: automatic decline if discharged within 24 months;
                manual review if 24-48 months; standard processing if >48 months.
                Revenue requirement: minimum $250K annual revenue for 2 consecutive
                years. Time in business: minimum 2 years. Industry exclusions:
                cannabis, gambling, adult entertainment, cryptocurrency mining.""",
                metadata={"regulation": "Internal Policy", "section": "CP-2026-04",
                          "applicability": "sme_lending", "severity": "binding"}
            ),
            Document(
                page_content="""UDAAP (Unfair, Deceptive, or Abusive Acts or Practices):
                Underwriting models must not produce disparate impact on protected
                classes. AI/ML models used in credit decisions must pass fair lending
                testing: (1) Adverse Impact Ratio (AIR) must exceed 0.80 for all
                protected classes; (2) Marginal effects analysis must show no
                statistically significant disparate treatment; (3) proxy variables
                for protected characteristics must be tested. Model validation must
                occur annually per SR 11-7. LLM-generated explanations must be
                factually consistent with the actual model output.""",
                metadata={"regulation": "UDAAP", "section": "Fair Lending",
                          "applicability": "all_models", "severity": "critical"}
            ),
        ]

        splitter = RecursiveCharacterTextSplitter(
            chunk_size=500, chunk_overlap=50
        )
        chunks = splitter.split_documents(regulations)
        self.vectorstore.add_documents(chunks)

    def retrieve_relevant_regulations(
        self, query: str, k: int = 4
    ) -> List[Tuple[str, dict]]:
        """
        Retrieve top-k relevant regulatory chunks.
        The query is constructed from the application context.
        """
        results = self.vectorstore.similarity_search_with_score(query, k=k)
        return [
            (doc.page_content, doc.metadata)
            for doc, score in results
        ]

    def check_compliance(
        self,
        application_context: str,
        classical_scores: dict,
        decision: str
    ) -> dict:
        """
        LLM-powered compliance check using RAG-retrieved regulations.

        THIS IS WHERE LLM + RAG SHINES: The LLM reasons over retrieved
        regulations to determine if the decision is compliant. A classical
        model cannot do this — it requires natural language understanding
        of legal text.
        """
        regulations = self.retrieve_relevant_regulations(application_context)
        reg_text = "\n\n".join([r[0] for r in regulations])
        reg_sources = [r[1] for r in regulations]

        prompt = f"""You are a senior compliance officer at a regulated bank.

RETRIEVED REGULATIONS:
{reg_text}

APPLICATION CONTEXT:
{application_context}

CLASSICAL MODEL SCORES:
{classical_scores}

PROPOSED DECISION: {decision}

Analyze whether this decision complies with all retrieved regulations.
Check specifically for:
1. FCRA adverse action requirements (if declining)
2. ECOA non-discrimination and notification requirements
3. Basel III capital adequacy for the risk grade
4. Internal policy thresholds (CP-2026-04)
5. UDAAP fair lending considerations

Return JSON with: is_compliant (bool), violated_regulations (list),
applicable_guidelines (list), risk_tier (standard/elevated/prohibited)."""

        response = self.llm.invoke(prompt)
        return {
            "regulations_retrieved": reg_text,
            "sources": reg_sources,
            "compliance_analysis": response.content
        }
Join the conversation! Your thoughts help the community grow.