
Introduction
Gone are the days when AI could only process text or numbers. Welcome to the era of Multimodal AI intelligent systems that can see images, understand speech, analyze video, and even generate creative outputs across all these formats simultaneously. This breakthrough is reshaping industries and redefining the boundaries of human-machine interaction.
What is Multimodal AI?
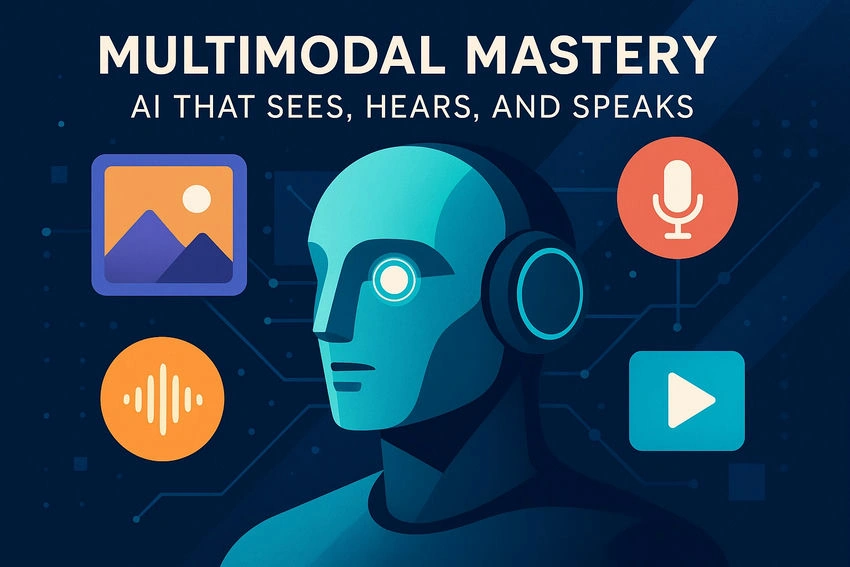
Multimodal AI refers to systems capable of processing and integrating multiple types of input text, images, audio, and video to deliver richer, more contextualized responses. These agents can,
- Interpret a photo and describe it.
- Watch a video and summarize key scenes.
- Listen to audio and detect emotion.
- Combine text and visual cues to make decisions.
The goal? To make AI more human-like in its understanding of the world.
Why Multimodality Matters?
Humans don’t rely on just one sense, and neither should intelligent machines. By combining visual, auditory, and linguistic data, AI agents can.
- Understand complex scenes and environments.
- Answer questions about charts, photos, or recordings.
- Engage in interactive storytelling and simulations.
- Make better predictions with context from multiple sources.
This unlocks a whole new dimension of immersive and intuitive experiences.
How does It Work?
Multimodal agents are powered by architectures like.
- Transformer models that merge multiple data streams.
- Vision-language models (VLMs) like GPT-4o, Gemini, and Claude.
- Multimodal embedding spaces where different data types are converted into a shared format.
These systems are trained on huge multimodal datasets image-caption pairs, video-transcripts, audio-tagged clips allowing them to generalize across modes.
Real-World Applications
| Industry | Use Case Example |
|---|---|
| Healthcare | AI that analyzes medical images and explains them in natural language. |
| Education | Multimodal tutors that explain diagrams and read text aloud. |
| Retail | Virtual stylists that see what you wear, listen to your preferences, and suggest outfits. |
| Entertainment | AI that composes music based on images or tells stories from videos. |
| Accessibility | Helping the visually impaired with AI that describes the world in real time. |
Challenges & Risks
- Data complexity: Handling varied input formats reliably.
- Bias: Visual/audio biases can skew results.
- Model size: Multimodal models are often huge and require massive compute.
- Interpretability: Understanding how decisions were made across modes.
Ongoing research focuses on compression, alignment, and ethics to tackle these challenges.
What’s Next?
By 2026, we expect agents that.
- Simultaneously analyze live video feeds + audio calls.
- Create complete multimedia content (text + image + audio + animation).
- Serve as collaborative assistants in AR/VR and metaverse environments.
Multimodal AI is not just a trend; it’s the future of intelligent systems.
FAQs
Q 1. What does “multimodal” mean in AI?
A. It means the ability to process and combine different data types like text, images, and audio.
Q 2. Is GPT-4 multimodal?
A. Yes, GPT-4o supports multimodal input including text, vision (image), and audio.
Q 3. What’s the benefit of multimodal agents?
A. They understand context better and deliver more accurate, human-like responses.
Q 4. Which industries benefit most?
A. Healthcare, education, accessibility, e-commerce, and creative arts are seeing major impact.
Q 5. Are there any open-source multimodal models?
A. Yes, models like CLIP, LLaVA, and BLIP are available for experimentation.
Q 6. Do these models require special hardware?
A. Generally yes, due to large model sizes and multiple data streams.
Q 7. Can multimodal agents understand sarcasm or tone?
A. With audio input, they can detect tone/emotion better than text-only models.
Q 8. How do they learn across modes?
A. Through aligned datasets (e.g., image-caption pairs, audio transcripts) and shared embeddings.
Q 9. What’s the difference between multimodal and cross-modal?
A. Multimodal = multiple inputs together. Cross-modal = using one type to affect another (e.g., generating image from text).
Q 10. What’s the future of multimodal AI?
A. Integrated digital co-pilots that function across apps, senses, and environments seamlessly.
Join the conversation! Your thoughts help the community grow.