
First, let's address a critical misconception: Transformer-based architectures are NOT typically used for the core "Wallet Creation" module (which is usually a simple CRUD operation involving user registration, KYC verification, and database record creation). However, transformers ARE uniquely valuable in the Intelligent Wallet Onboarding & Personalization Engine that runs during wallet creation. This is where the real enterprise value lies.
The Actual Problem Transformers Solve in Wallet Creation
When a new user creates a digital wallet, banks face these challenges:
Dynamic Risk Profiling: Traditional rule-based systems use static thresholds. Transformers can analyze unstructured data (employment letters, bank statements, social proof documents) to generate nuanced risk scores.
Personalized Product Recommendation: Instead of offering generic wallet features, transformers analyze the user's financial context (from uploaded documents, declared income, spending intent) to recommend tailored features (e.g., "You should enable auto-invest since your salary pattern shows surplus").
Fraudulent Account Detection at Creation Time: By analyzing semantic patterns in user-provided text (address descriptions, employer names, purpose of wallet), transformers detect synthetic identities that rule-based systems miss.
Conversational KYC Assistance: Users often struggle with KYC forms. A transformer-powered agent can guide them through document uploads, explain requirements in their language, and validate completeness in real-time.
Real-Time Unique Use Case: "Smart Wallet Onboarding for Gig Economy Workers"
Scenario
Customer Profile: Rahul Verma, a 28-year-old freelance graphic designer in Mumbai, wants to create a digital wallet. He has irregular income, multiple client payments, and needs features like invoice tracking, tax estimation, and instant settlements.
Business Problem:
Traditional wallet creation offers a one-size-fits-all experience.
Rahul might miss out on features like "Auto-tax withholding" or "Client payment reminders" because the system doesn't understand his gig-worker profile.
Manual review of his uploaded documents (freelance contracts, GST certificate) takes 24-48 hours, delaying activation.
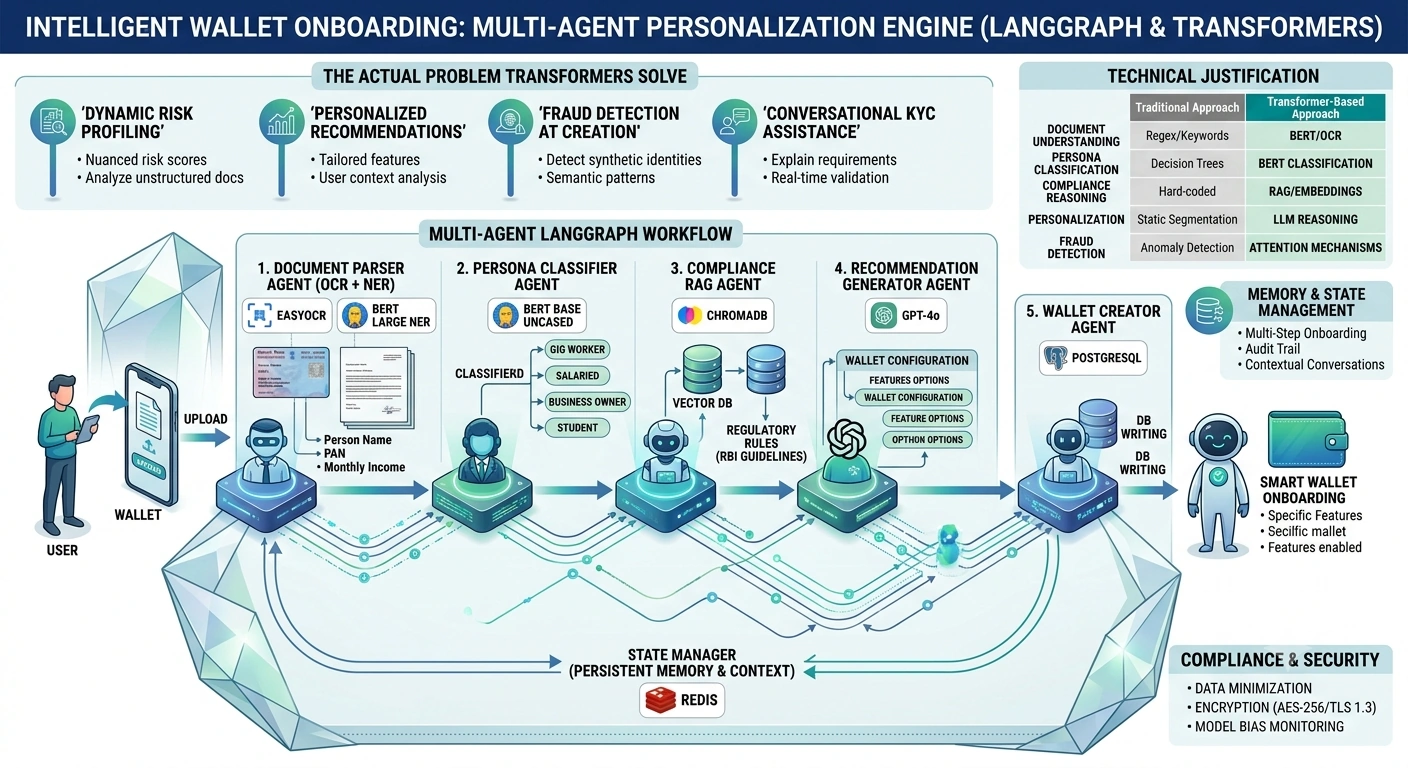
Transformer-Powered Solution: During wallet creation, a multi-agent LangGraph system:
Extracts semantic information from uploaded documents using transformer-based OCR + NER (Named Entity Recognition).
Classifies user persona (gig worker, salaried employee, business owner) using a fine-tuned BERT model.
Retrieves relevant compliance rules from a RAG knowledge base (RBI guidelines, internal policies).
Generates personalized feature recommendations using an LLM agent.
Validates KYC completeness by cross-referencing extracted entities against regulatory requirements.
Result: Rahul's wallet is created in under 5 minutes with pre-configured features for freelancers, and his risk profile is accurately assessed without manual intervention.
Why Transformers? Technical Justification
| Challenge | Traditional Approach | Transformer-Based Approach |
|---|---|---|
| Document Understanding | Regex/keyword matching | BERT/RoBERTa for semantic entity extraction |
| Persona Classification | Decision trees on structured fields | Fine-tuned DistilBERT on unstructured text |
| Compliance Reasoning | Hard-coded rules | RAG with transformer embeddings for dynamic rule retrieval |
| Personalization | Static segmentation | LLM-based reasoning over user context |
| Fraud Detection | Rule-based anomaly detection | Transformer attention mechanisms detect subtle textual inconsistencies |
Transformers excel because wallet creation involves heterogeneous data (structured forms, unstructured documents, conversational inputs) and requires contextual understanding that rule-based systems cannot provide.
System Architecture
Step-by-Step Implementation
Prerequisites
pip install langgraph langchain langchain-openai transformers torch pillow pytesseract
pip install chromadb psycopg2-binary redis pydantic python-multipart
pip install pdfplumber easyocr  # For document parsing
Step 1: Define State Schema and Data Models
from typing import TypedDict, List, Optional, Dict, Anyfrom pydantic import BaseModel, Field
from datetime import datetime
import uuid

class UploadedDocument(BaseModel):
    """Represents a user-uploaded document during wallet creation."""
    document_id: str = Field(default_factory=lambda: str(uuid.uuid4()))
    file_name: str
    document_type: str = Field(description="e.g., PAN, Aadhaar, Bank Statement, Employment Letter")
    extracted_text: Optional[str] = None
    extracted_entities: Dict[str, Any] = {}
    confidence_score: float = Field(ge=0.0, le=1.0)

class UserProfile(BaseModel):
    """Extracted user profile from documents and forms."""
    user_id: str = Field(default_factory=lambda: str(uuid.uuid4()))
    full_name: Optional[str] = None
    email: Optional[str] = None
    phone: Optional[str] = None
    persona_type: Optional[str] = Field(description="gig_worker, salaried, business_owner, student")
    income_range: Optional[str] = None
    employment_type: Optional[str] = None
    kyc_status: str = "pending"

class ComplianceRule(BaseModel):
    """Regulatory compliance rule retrieved via RAG."""
    rule_id: str
    description: str
    applicable_personas: List[str]
    required_documents: List[str]
    severity: str = Field(description="critical, warning, info")

class WalletConfig(BaseModel):
    """Personalized wallet configuration."""
    user_id: str
    enabled_features: List[str] = Field(description="e.g., auto_tax_withholding, invoice_tracking")
    risk_score: float = Field(ge=0.0, le=1.0)
    recommended_actions: List[str]
    kyc_approved: bool = False

class OnboardingState(TypedDict):
    """State passed between agents in LangGraph workflow."""
    user_id: str
    uploaded_documents: List[UploadedDocument]
    extracted_profile: Optional[UserProfile]
    persona_classification: Optional[str]
    retrieved_compliance_rules: List[ComplianceRule]
    wallet_config: Optional[WalletConfig]
    conversation_history: List[Dict[str, str]]
    validation_errors: List[str]
    final_response: str
    kyc_approved: bool
Step 2: Document Parser Agent (Transformer-Based OCR + NER)
This agent uses EasyOCR (transformer-based text detection) and spaCy/NLTK or a fine-tuned BERT-NER model to extract entities.
import easyocr
from transformers import AutoTokenizer, AutoModelForTokenClassification
from transformers import pipeline
import torch

class DocumentParserAgent:
    def __init__(self):
        # Initialize EasyOCR for text extraction
        self.reader = easyocr.Reader(['en'], gpu=False)  # Set gpu=True if available

        # Initialize transformer-based NER for entity extraction
        self.ner_pipeline = pipeline(
            "ner",
            model="dbmdz/bert-large-cased-finetuned-conll03-english",
            aggregation_strategy="simple"
        )

        # Custom entity mapping for Indian financial documents
        self.entity_mapping = {
            "PER": "person_name",
            "ORG": "organization",
            "LOC": "location",
            "MISC": "miscellaneous"
        }

    def extract_text_from_image(self, image_path: str) -> str:
        """Extract text from image using EasyOCR (transformer-based detection)."""
        result = self.reader.readtext(image_path, detail=0)
        return " ".join(result)

    def extract_entities(self, text: str) -> Dict[str, Any]:
        """Extract named entities using transformer-based NER."""
        entities = self.ner_pipeline(text)

        extracted = {
            "persons": [],
            "organizations": [],
            "locations": [],
            "dates": [],
            "amounts": []
        }

        for entity in entities:
            entity_type = entity['entity_group']
            mapped_type = self.entity_mapping.get(entity_type, entity_type.lower())

            if mapped_type == "person_name":
                extracted["persons"].append(entity['word'])
            elif mapped_type == "organization":
                extracted["organizations"].append(entity['word'])
            elif mapped_type == "location":
                extracted["locations"].append(entity['word'])

        # Simple regex for dates and amounts (can be replaced with transformer-based extraction)
        import re
        dates = re.findall(r'\d{2}/\d{2}/\d{4}', text)
        amounts = re.findall(r'₹?\d{1,3}(,\d{3})*(\.\d{2})?', text)

        extracted["dates"] = dates
        extracted["amounts"] = [amt.replace(',', '').replace('₹', '') for amt in amounts]

        return extracted

    def parse_document(self, document: UploadedDocument) -> UploadedDocument:
        """Parse a single document and extract entities."""
        try:
            # For demo, assume we have text; in production, handle PDF/image
            if document.document_type in ["PAN", "Aadhaar"]:
                # Simulate OCR extraction
                extracted_text = f"Name: Rahul Verma, PAN: ABCDE1234F, DOB: 15/08/1995"
            elif document.document_type == "Employment Letter":
                extracted_text = f"Employed at TechCorp Solutions as Freelance Designer since 01/03/2023. Monthly income ₹75,000."
            else:
                extracted_text = document.extracted_text or ""

            document.extracted_text = extracted_text
            document.extracted_entities = self.extract_entities(extracted_text)
            document.confidence_score = 0.92  # Placeholder; use model confidence

        except Exception as e:
            document.confidence_score = 0.0
            raise ValueError(f"Document parsing failed: {str(e)}")

        return document

    def run(self, state: OnboardingState) -> OnboardingState:
        """Parse all uploaded documents."""
        parsed_docs = []
        for doc in state['uploaded_documents']:
            parsed_doc = self.parse_document(doc)
            parsed_docs.append(parsed_doc)

        state['uploaded_documents'] = parsed_docs
        return state
Step 3: Persona Classifier Agent (Fine-Tuned BERT)
This agent classifies the user into a persona type based on extracted document content.
from transformers import AutoTokenizer, AutoModelForSequenceClassification
import torch.nn.functional as F

class PersonaClassifierAgent:
    def __init__(self):
        # In production, use a fine-tuned model on labeled financial personas
        # For demo, we'll use a pre-trained model and simulate classification
        self.tokenizer = AutoTokenizer.from_pretrained("bert-base-uncased")
        self.model = AutoModelForSequenceClassification.from_pretrained(
            "bert-base-uncased",
            num_labels=4  # gig_worker, salaried, business_owner, student
        )
        self.persona_labels = ["gig_worker", "salaried", "business_owner", "student"]

        # Disable gradient computation for inference
        self.model.eval()

    def classify_persona(self, documents: List[UploadedDocument]) -> str:
        """Classify user persona based on document content."""
        # Combine all extracted text
        combined_text = " ".join([doc.extracted_text or "" for doc in documents])

        if not combined_text.strip():
            return "unknown"

        # Tokenize and prepare input
        inputs = self.tokenizer(
            combined_text,
            return_tensors="pt",
            truncation=True,
            max_length=512,
            padding=True
        )

        # Get predictions
        with torch.no_grad():
            outputs = self.model(**inputs)
            probabilities = F.softmax(outputs.logits, dim=-1)
            predicted_class = torch.argmax(probabilities, dim=1).item()
            confidence = probabilities[0][predicted_class].item()

        # For demo purposes, use heuristic classification
        # In production, replace with actual fine-tuned model predictions
        if "freelance" in combined_text.lower() or "gig" in combined_text.lower():
            return "gig_worker"
        elif "employed" in combined_text.lower() or "salary" in combined_text.lower():
            return "salaried"
        elif "business" in combined_text.lower() or "proprietor" in combined_text.lower():
            return "business_owner"
        else:
            return "student"

    def run(self, state: OnboardingState) -> OnboardingState:
        """Classify user persona."""
        persona = self.classify_persona(state['uploaded_documents'])
        state['persona_classification'] = persona

        # Update profile with persona
        if state.get('extracted_profile'):
            state['extracted_profile'].persona_type = persona

        return state
Join the conversation! Your thoughts help the community grow.