
Google has expanded its Gemma 3 open model family with Gemma 3 270M — a lightweight 270-million parameter model built for hyper-efficient, task-specific fine-tuning. While not aimed at complex conversations, it delivers exceptional instruction-following, structured text output, and performance efficiency, making it ideal for on-device AI and specialized production workloads.
Download the Gemma 3 270M models from Hugging Face, Ollama, Kaggle, LM Studio, or Docker.
This launch follows the success of Gemma 3, Gemma 3 QAT, and Gemma 3n, as downloads across the “Gemmaverse” surpassed 200 million last week.
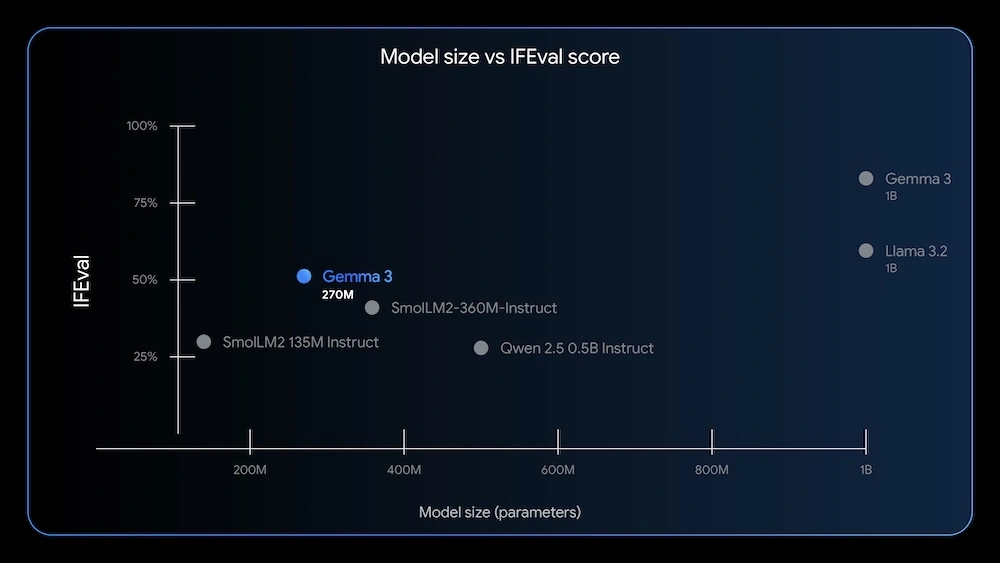
Image Courtesy: Google
Key Features of Gemma 3 270M
-
Compact but Capable:
-
270M parameters — 170M for embeddings (256K vocabulary) + 100M for transformer blocks.
-
Handles rare tokens and domain-specific terms with ease.
-
-
Extreme Energy Efficiency:
-
INT4-quantized model consumed just 0.75% battery for 25 conversations on a Pixel 9 Pro SoC.
-
Ideal for resource-constrained devices and low-power deployments.
-
-
Instruction Following:
-
Pre-trained and instruction-tuned checkpoints available.
-
Strong out-of-the-box adherence to general instructions.
-
-
Production-Ready Quantization:
-
Quantization-Aware Training (QAT) for INT4 precision with minimal performance loss.
-
Why Choose Gemma 3 270M
-
High-Volume, Defined Tasks: Perfect for sentiment analysis, entity extraction, compliance checks, and text-to-structure processing.
-
Ultra-Low Inference Costs: Run on lightweight infrastructure or entirely on-device.
-
Rapid Fine-Tuning: Smaller size means faster experiments — hours instead of days.
-
Privacy-First AI: Process sensitive data locally without cloud transfer.
-
Specialized Model Fleets: Deploy multiple fine-tuned models for different use cases without breaking the budget.
Real-World Applications
The specialization-first approach has already proven effective. Adaptive ML and SK Telecom fine-tuned a Gemma 3 4B model for multilingual content moderation, outperforming much larger proprietary models on the task.
For creative applications, developers like Joshua (@xenovacom) from Hugging Face have used Gemma 3 270M to power offline web apps such as a Bedtime Story Generator using Transformers.js — demonstrating its potential for fast, private, and interactive experiences.
Availability
Gemma 3 270M is available now for developers to download, fine-tune, and integrate into custom AI workflows.
Try the models on Vertex AI or with popular inference tools like llama.cpp Gemma.cpp, LiteRT, Keras, and MLX.
Join the conversation! Your thoughts help the community grow.