
Data
In data science, data is either categorical or continuous form or data source as per video, everything which can be recorded has been data.
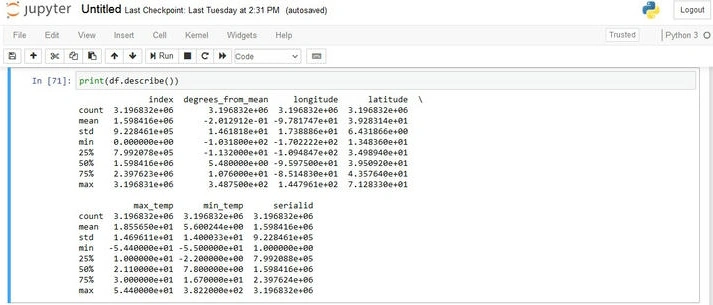
Outliers: When we collect or buy any data, we fill it with data that is beyond the minimum data value or maximum data value, and we call it outlier.
Outliers and Their Treatment

Outliers are data points that deviate significantly from the rest of the dataset, results and affecting the performance of machine learning models. Properly identifying and treating outliers is essential for maintaining the integrity of data analysis.
How to Treat?
Looking at Graphs
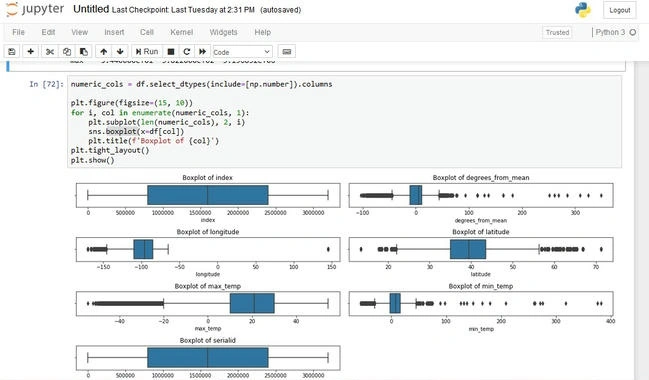
- Box Plot: This graph shows how your data spreads out. Points that are far outside the main range are likely outliers.
- Scatter Plot: It shows data points scattered on a graph. If a point is far away from the others, it might be an outlier.
- Histogram: This divides data into bars to show its spread. If a bar looks very different from the rest, it could point to an outlier.
- When to use: Great for quickly spotting issues in small datasets, but might miss things in bigger or complex data.
Math-Based Methods
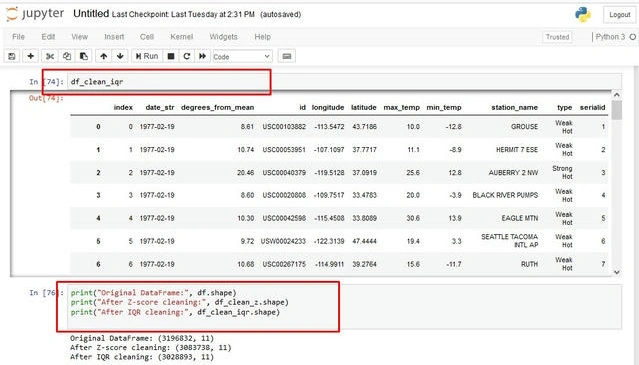
- Z-Score: This checks how far a data point is from the average. If it’s more than 3 steps away (or less than -3), it’s probably an outlier. Works best when data follows a normal pattern.
- Interquartile Range (IQR): Split your data into four parts and look at the middle half (Q1 to Q3). Points below Q1−1.5×IQR or above Q3+1.5×IQR are outliers. This works even if your data isn’t normal.
Treatment of Outliers
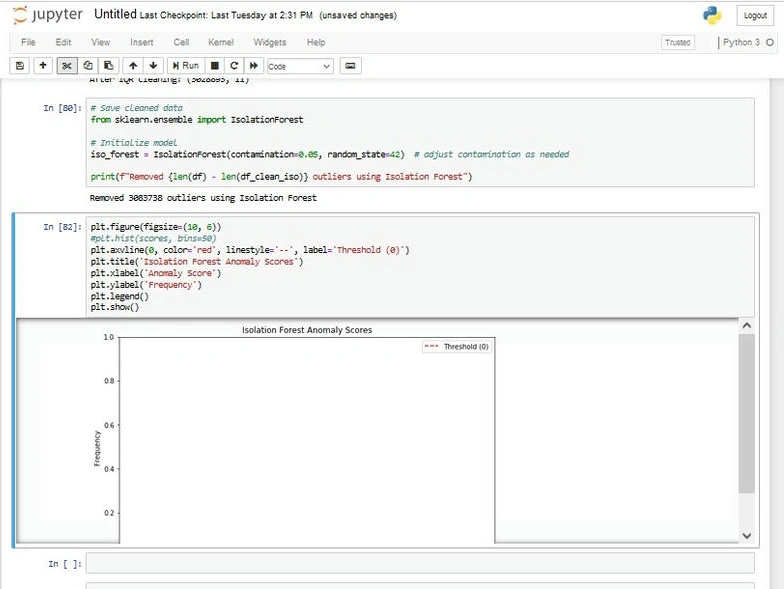
- Removal: Completely eliminating outlier data points from the dataset. This approach is straightforward but may lead to loss of valuable information, especially if outliers are useful.
- Capping: Setting upper and lower limits for outlier values, effectively reducing their impact without removing them entirely.
- Transformation: Applying mathematical transformations reduce skewness and lessen the effect of outliers on statistical analyses.
- Imputation: Replacing outlier values with more typical values, such as the mean or median of the dataset.
- Modeling Separately: In some cases, it may be beneficial to create a separate model for outliers or treat them as a distinct category within the analysis.

Join the conversation! Your thoughts help the community grow.